Thursday, October 8, 2026ArchiveSearchAsk the paper

The Computomatix Times

All the posts fit to save — curated from @computomatix's bookmarks & likes on X

Search

289 stories

Jev Claims to Replace Focus Groups by Scoring Ads Automatically

Jev Claims to Replace Focus Groups by Scoring Ads Automatically▶

Matthew Berman says the Jev tool scrolled 723 ads and scored them as 30 buyer personas at a cost of 22 cents, with availability planned through StealAds and MCP. A quoted post describes Jev breaking down 724 live ads from 37 brands in 40 seconds.

Original post · 1 min read
jev KILLED the focus group.

it scrolled 723 ads as 30 buyer personalities

21,690 stop or scroll decisions. 22 cents.
(will be avail in @StealAds + mcp)
Matthew Berman @TheMattBerman
jev is INSANE.

in 40 seconds it broke down 724 live ads from 37 brands.

every hook. every format. offer. cta. awareness stage. landing page mismatch. used 9 cents of tokens.
(will be avail in @stealads + mcp)
♥ 1.2K · ⟲ 79 · 👁 134.4KView on X ↗

Dmitry Korzhov Outlines Jev Workflows for Marketers at Low Cost

Dmitry Korzhov Outlines Jev Workflows for Marketers at Low Cost▶

Dmitry Korzhov lists seven marketing workflows Jev can accelerate, including ad library scans, creative scoring, search term sorting, fatigue detection and lead scoring. He says it runs through the Ryze AI app and an MCP connector for under $3, and quotes Ira Bukht claiming SEO/GEO audit costs dropped 90%.

Original post · 1 min read
Jevmaxxing for marketers

Jev can speed up most marketing workflows 30x and do it for < $3:

1/ Scan the whole Meta Ad Library
-> It reads every live ad in your category and tags each one by hook, format, offer and days running

2/ Find the ad patterns that survive
-> It compares formats by how many ads are still live after 60 days, so you know what lasts before you test it

3/ Score briefs before you shoot
-> Your LLM writes the briefs, Jev scores each on hook, brand fit and survival odds, and only the top ones get made

4/ Sort search terms
-> It asks "is this query from a buyer?" across the full Google Ads report, so negatives land the same night

5/ Catch fatigue early
-> For every ad with frequency up and CTR down, it picks replace, refresh or leave

6/ Check ad to landing page match
-> It scores whether the page delivers what the ad promised, the cheapest CVR fix in most accounts

7/ Score every lead
-> It rates each form fill 0 to 100 against your ideal customer within seconds, so Google and Meta learn to find more of the good ones

Available in the Ryze AI app and MCP/Claude Connector, link in the 1st comment 👇
Ira Bodnar @irabukht
Jev dropped the price of SEO/GEO fixes by 90%

Agents that audit and fix a client's SEO/GEO used to cost us ~$250

Here's where the savings come from:

1/ 30x faster reads of Search Console and PostHog/Mixpanel data

2/ 30x faster checks of what ChatGPT searches on Bing

3/ 30x faster modeling of what users ask Gemini and Claude

4/ 30x faster scans of who ChatGPT and Claude cite

5/ 30x faster analysis of the sources behind those citations

6/ 30x faster gap analysis: why they get cited and we don't

7/ 30x faster fixes across 1,000s of pages on large client sites

8/ 30x faster sorting of wh…
♥ 1.4K · ⟲ 106 · 👁 318.3KView on X ↗

Codila Presents Jev and GrokBot Agent Setup Guide With Typesafe

Codila Presents Jev and GrokBot Agent Setup Guide With Typesafe▶

Codila describes a seven-step setup connecting the Jev decision layer with GrokBot on a local computer via a Typesafe API key and a usage router skill. The post promotes a GitHub repo and deep-dive article, and quotes a claim that Jev is the 'Internet moment' for AI agents.

Original post · 1 min read
Jev + GrokBot is the best AI agent system I’ve built in my life

It just made my setup CHEAPER and FASTER than what 95% of people are running...

setup takes literally 7 minutes:

prompt → GrokBot → Jev decision → GrokBot execution → result

step 1 → open @typesafeai , create API key (keep it off chat paste)

step 2 → tell Grok Bot: store TYPESAFE_API_KEY in the secure field

step 3 → prompt Grok Bot: install typesafe-sdk on Agent Computer + smoke system_one (Choice)

step 4 → tell Grok Bot: build the usage lab (router, dry-run, config, logs) - or clone Github below

step 5 → add skill jev-usage-router: before browser / research / retry / extra bot → call the router, honor action

step 6 → stay shadow first, read logs, then active when you trust it - kill switch: bypass jev or enabled: false

step 7 → flip active: GrokBot obeys route - Jev decides - GrokBot executes - humans control irreversible actions

the result: Jev + GrokBot the best and fastest agent running directly on your computer rn, I’ve already tested it on routine tasks - and the results are genuinely incredible

You can come up with endless ways to use Jev + GrokBot - but the most important thing is to install it as soon as possible

Copy this 2028 setup, explore my repo below - then read the full Jev deep dive ↓
codila @0xCodila
Jev is the "Internet" moment for the AI industry

It tells your agents and LLMs what to do next, in milliseconds and at almost zero cost

If you set it up correctly, you will have the AI engineer’s stack for 2028

In this article, I show you how
♥ 2.4K · ⟲ 257 · 👁 383.7KView on X ↗

Hiten Shah Argues Agent Verification Will Dominate the Agent Stack

Hiten Shah comments on the engineering effort behind Devin's Cloud Mac, which Cognition's Jake Kelley describes as rebuilt in Rust, and argues that verifying an agent's work will consume much of the stack. The quoted post covers disk, networking, provisioning, VNC and computer use.

Original post · 1 min read
This is a wild amount of engineering to solve what is becoming a very important problem.

How does the agent know the work actually worked?

I suspect verification ends up eating a lot more of the agent stack than people expect.
Jon Kelley @jkelleyrtp
Several months of work went into building Devin's Cloud Mac!

We had to rebuild its disk, networking, provisioning, VNC, and computer use from scratch, in Rust.

Read my first X article about how it all works 😊
♥ 67 · ⟲ 1 · 👁 14.7KView on X ↗

AI Search Points to Nimble as Open Alternative to Jev

AI Search Points to Nimble as Open Alternative to Jev

AI Search says Jev is closed and available only via API, and offers Nimble, a GitHub project from Bespoke Labs, as an open version that performs comparably. The post links to the Nimble repository.

Original post · 1 min read
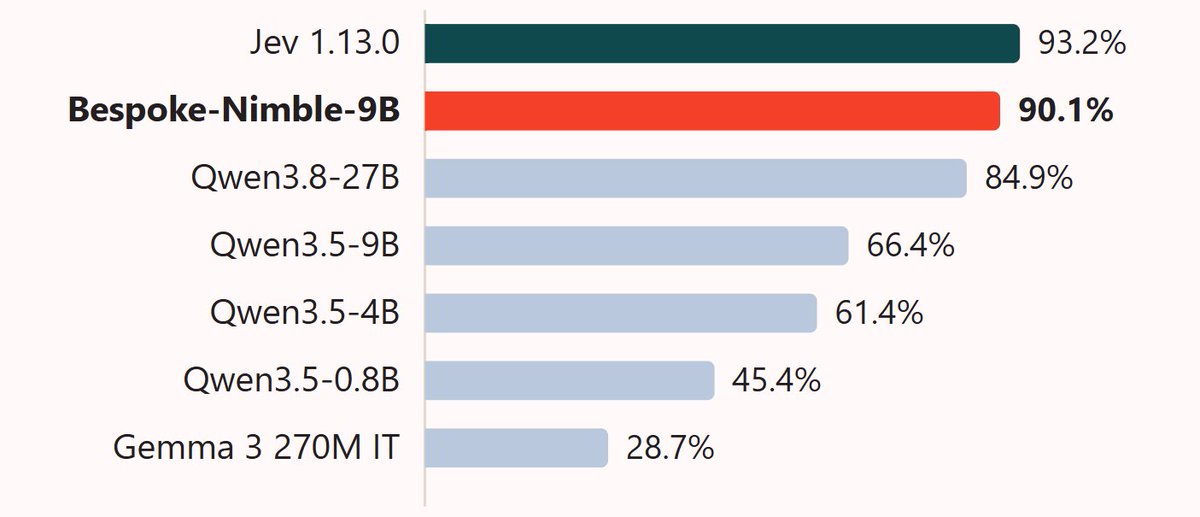
Jev is not open-source and only available via API.

Here's an open version called Nimble which performs just as well.

github.com/bespokelabsai/nimble
github.comGitHub - bespokelabsai/nimble: Local typed decisions, contrastive data curation, and model evaluation.Local typed decisions, contrastive data curation, and model evaluation. - bespokelabsai/nimble
♥ 3.3K · ⟲ 254 · 👁 168.8KView on X ↗

TypeSafe Releases Open-Source Skill Pack for Codex and Cursor

GitHub - typesafe-ai/skills: Agent skills for building with TypeSafe's System One API

The typesafe-ai/skills GitHub repository provides agent skills that let Codex or Cursor build typed decide, tool, and evaluate loops against the TypeSafe System One API. It has about 440 stars.

Original post · 1 min read
typesafe-ai/skills is a skill pack for TypeSafe System One. Drop it into Codex or Cursor so agents get typed decide, tool, and evaluate loops. 440 stars.

github.com/typesafe-ai/skills
github.comGitHub - typesafe-ai/skills: Agent skills for building with TypeSafe's System One APIAgent skills for building with TypeSafe's System One API - typesafe-ai/skills
♥ 1.3K · ⟲ 108 · 👁 81.1KView on X ↗

classifier.dev Offers Free Zero-Shot Text Classification Over HTTP

classifier.dev Offers Free Zero-Shot Text Classification Over HTTP

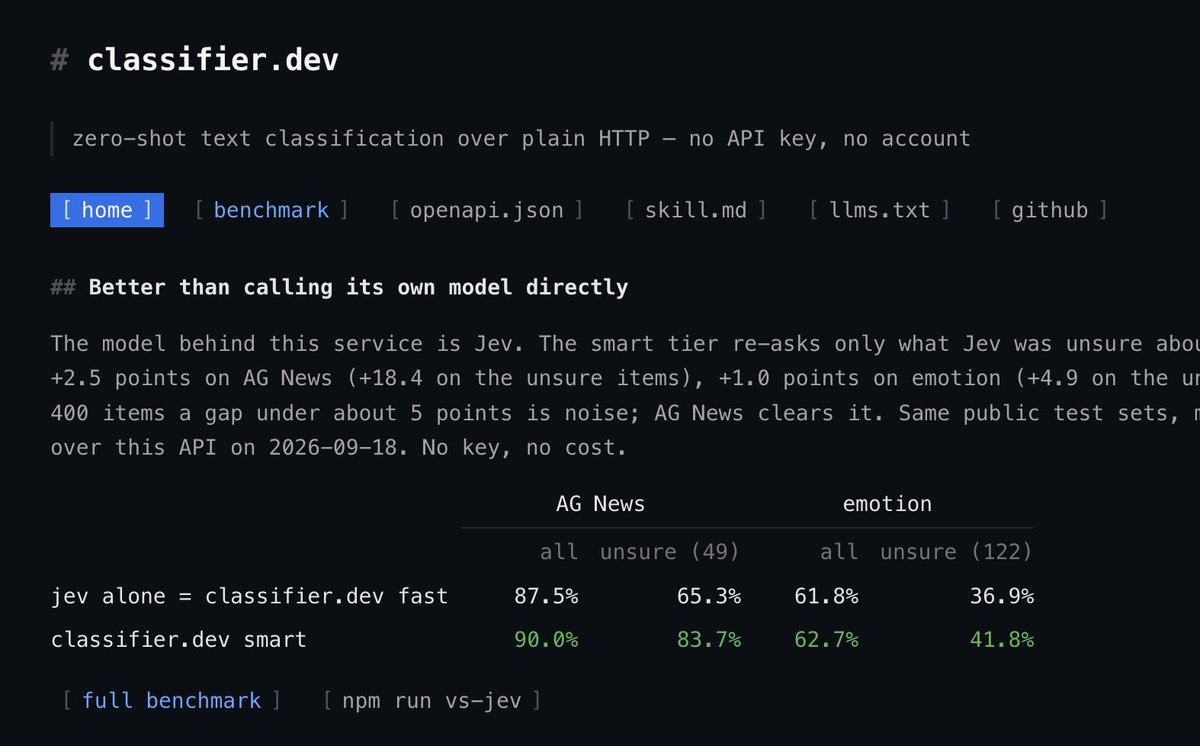
Michael announces classifier.dev as a free service that claims to outperform Jev, offering zero-shot text classification over plain HTTP with no API key or account.

Original post · 1 min read
classifier.dev now outperforms jev and is free

go nuts guys
classifier.devclassifier.devZero-shot text classification over plain HTTP. No API key, no account.
♥ 5.9K · ⟲ 355 · 👁 504.9KView on X ↗

Guillermo Rauch Says Generative UI Has Been Achieved Externally

Vercel's Guillermo Rauch says generative UI has been achieved externally, quoting a post by @ctatedev about an experiment combining json-render and jev that renders custom components and actions in milliseconds.

Original post · 1 min read
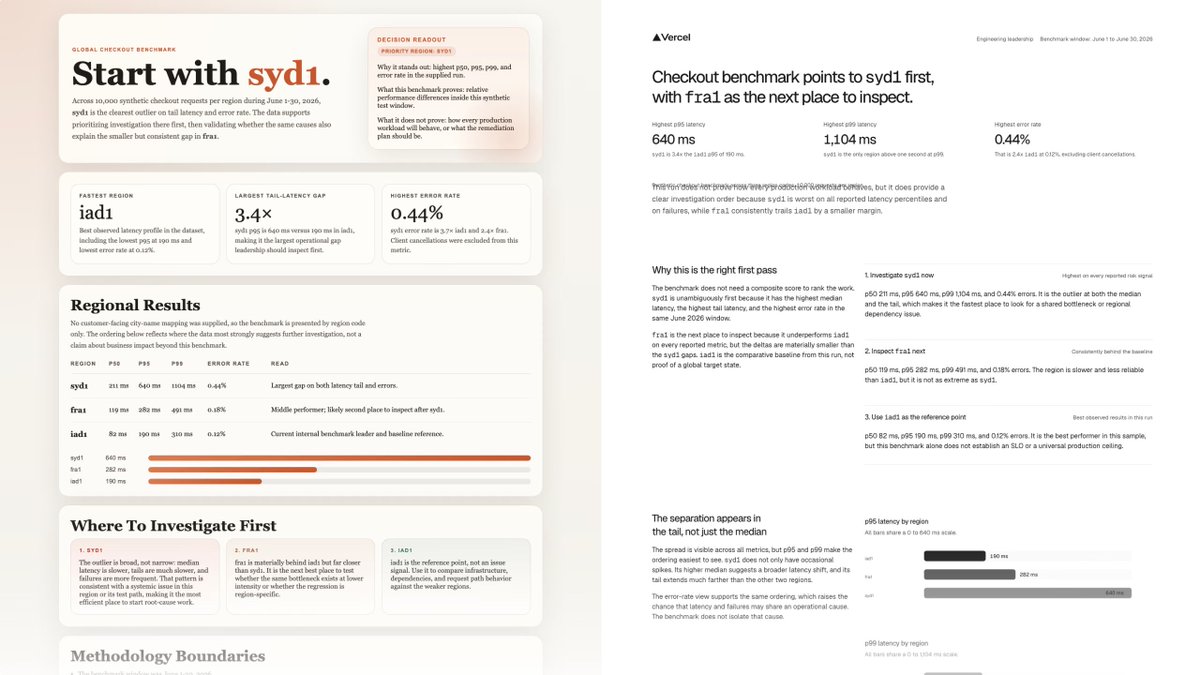
Jev Generative UI has been achieved externally
Chris Tate @ctatedev
New experiment: json-render + jev

The future Generative UI is instant

Your components, your actions, your design system

Rendered in milliseconds
♥ 4.5K · ⟲ 155 · 👁 532.9KView on X ↗

Virat Singh Adds Jev to AI Hedge Fund for Faster Trading Decisions

Virat Singh Adds Jev to AI Hedge Fund for Faster Trading Decisions▶

Virat Singh says he added Jev to his AI Hedge Fund project, claiming frontier-level trading decisions 100 times faster and cheaper than an LLM. The workflow sets strategy, picks tickers and backtests, now running in seconds.

Original post · 1 min read
I added Jev to the AI Hedge Fund.

We now get frontier-level trading decisions, 100x faster and cheaper than an LLM.

How it works:
1 • set strategy
2 • pick tickers
3 • backtest with Jev

System now runs in seconds, not minutes.
♥ 1.1K · ⟲ 71 · 👁 93.5KView on X ↗

Marcel Pociot Builds Macos Downloads Organizer Using Only Jev

Marcel Pociot Builds Macos Downloads Organizer Using Only Jev▶

Marcel Pociot says he built a macOS app that monitors the Downloads folder and applies customizable rules, such as moving invoices to a special folder with a corrected filename, using only Jev without other LLM calls.

Original post · 1 min read
Jev unlocks SO many awesome new ideas.

I built a macOS app that monitors my Downloads folder along with a customisable set of rules.

Is the downloaded file an invoice? Move it to a special folder with the correct filename.

No other LLM calls involved - just Jev!
♥ 1.2K · ⟲ 48 · 👁 139.9KView on X ↗

Jasper Li Open-Sources Workflow for Agent-Driven AI UGC Video Variants

Jasper Li announces an open-sourced workflow that lets an agent create AI user-generated-content videos, clone styles and generate variants at scale, positioned against Higgsfield, Seedance and MiniMax. A quoted post by Shengkun Ye describes the workflow as costing $0.03 per second.

Original post · 1 min read
You don’t need Higgsfield.
You don’t need Seedance.
You don’t need MiniMax.

We open-sourced the workflow so your agent can create AI UGC, clone any style, and generate variants at scale.

1 clone. 100 variants. 100M views.
Let your agent cook. 🔥
Shengkun Ye @shengkunye
We killed the $60 human UGC.

Introducing GPT-6 Astra for AI UGC.

Open-sourced the workflow to replicate viral videos for just $0.03/sec.

@hypitai × @MonidHQ
♥ 923 · ⟲ 68 · 👁 109.1KView on X ↗

Full Context Highlights Open Source Jev Tool for Fast Browser Agents

Full Context introduces Jev, an open source tool from Browser Use that reviews a page and picks the next action, such as clicking, typing, scrolling or retrying. The author suggests splitting work between a large model for planning and a small fast model for choosing clicks, and notes the claims are still being verified.

Original post · 1 min read
Just found Jev.

Jev looks at the page, sees the real buttons, and just picks: click this one, type here, scroll, wait, or done.

- Click this
- Scroll down
- Type this
- Buy / sell
- Retry or stop
- Send the job to another agent

That’s it.

This is useful for:
• Browser agents that need to be fast
• Auto QA
• Trading loops
• Agent routing
• Games / robots
• Anything where the AI has to choose an action over and over.

The real trick is splitting thinking from “what do I do next”. Big model does the hard thinking. And the small fast model just picks the next click.

Still looking into it, so forgive me for any false claims.

Open source here:
github.com/browser-use/jev-ultrafast
♥ 1.9K · ⟲ 160 · 👁 134.0KView on X ↗

Dex Horthy Argues Jev Fits Pipeline Design From 12-Factor Agents

Dex Horthy argues that Jev is a strong reason to revisit his 12-Factor Agents guidance, since tool calling can be split into classification and action. He recommends designing AI systems as pipelines that mix classification, structured data, deterministic code and small agent loops, citing a linked guide.

Original post · 1 min read
jev is the best excuse you could possibly have to go re-read 12 factor agents. Tool calling itself can be decomposed into classify+action,

if you learn to design ai programs as pipelines that switch breathlessly between classification, structuring data, deterministic code, AND small agent-shaped append-chat loops, then jev is a WONDERFUL building block

hlyr.dev/12fa
Dillon Mulroy @dillon_mulroy
i think jev is resonating with devs so well b/c it unlocks so many opportunities for composing ai into systems and products rather than ai _becoming_ the product/system

really does feel like it was a missing primitive
♥ 2.7K · ⟲ 137 · 👁 233.6KView on X ↗

Grok Bot Livestreams Three SpaceXAI Staff Building a Company in Three Days

Grok Bot announces a livestream in which SpaceXAI employees Matt Palmer, Lauren Tan and Roshan Sadanani attempt to build a company in three days using Grok Bot, starting with research, a plan and a product, with sessions on engineering, product and founding.

Original post · 1 min read
Three SpaceXAI employees are building a company in 3 days with Grok Bot. This is Day 1.

Matt Palmer (@mattyp), Lauren Tan (@poteto), and Roshan Sadanani (@roshan_s) start with research, a plan, and a product.

Live now, plus sessions for engineering, product, and founders.

x.com/i/broadcasts/1AxRnZbVpjaxl
♥ 11.0K · ⟲ 1.6K · 👁 4.9MView on X ↗

Anthropic Says Claude Writes 80% of Its Code, Strains CI

Anthropic Says Claude Writes 80% of Its Code, Strains CI

Addy Osmani reports Claude now writes 80% of Anthropic's code and engineers ship 8x more per quarter. The side effects include 10x more tests and a 25x rise in CI jobs over six months, which Anthropic addressed with a scaled test impact analysis.

Original post · 1 min read
At Anthropic, Claude now writes 80% of our code. Engineers ship 8x more code per quarter.

Side effect: Tests grew 10x. CI jobs up 25x in 6 months. Here's what helped us scale:

claude.com/blog/agentic-coding-is-straining-ci…
claude.comAgentic coding is straining CI. Here’s how we scaled test impact analysis at Anthropic | Claude by AnthropicOur CI job volume increased 25x over 6 months. We patched our test selection service three times before finding a sustainable solution.
♥ 5.0K · ⟲ 367 · 👁 789.3KView on X ↗

Sergey Karayev Outlines Multiplayer Cloud Agent Workflow

Sergey Karayev describes how his team runs Claude, Codex and other agents in the cloud where any teammate can join a session. Meetings launch subagents for research and implementation, and a Chief of Staff agent tracks review queues; he published a manifesto on the approach.

Original post · 1 min read
For over a year, my team has been working with AI agents in a fundamentally different way than most.

All of our Claude/Codex/Pi/etc agents run in the cloud, and any session is joinable by anyone on the team.

Each of our meetings has an agent that launches subagents to do research, draft posts, and implement features as we discuss things.

A Chief of Staff agent lets me know what's waiting for my review, and can talk to any person or agent on the team to resolve bottlenecks.

Working in this fundamentally multiplayer way has given us a preview of the way everyone will work soon, so I wrote up a short manifesto explaining

• the current problems
• principles for a great solution
• some things that are tricky to get right

Check it out, and let me know what you think!

multiplayer-ai.com
♥ 902 · ⟲ 74 · 👁 420.7KView on X ↗

Shopify Seeks Feedback on Agentic Commerce Developer Docs

Agentic commerce

Gil from Shopify asks developers how the company can improve its UCP and agentic commerce documentation. The linked docs describe building AI agents that authenticate with Shopify, search the catalog, build carts and checkouts, and monitor orders via the Universal Commerce Protocol.

Original post · 1 min read
How can we (Shopify) improve our UCP and related agentic commerce docs? shopify.dev/docs/agents

I have some ideas but would love to hear from all of you. 🤔
shopify.devAgentic commerceBuild AI agents that authenticate with Shopify, search the Catalog, build carts and checkouts, and monitor orders using the Universal Commerce Protocol (UCP).
♥ 28 · ⟲ 3 · 👁 2.3KView on X ↗

Hiten Shah Spotlights Builders Behind Featured Grok Bots

Hiten Shah tags a list of builders whose Grok Bots he featured, following his review of 407 public Grok Bots and the specific jobs people are assigning them. The post promotes the bot creators and his own experiments.

Original post · 1 min read
These are the builders behind the Grok Bots I featured today:

@matt_silberman @clairevo @mattyp @dannymacias @Andrew51786 @mvanhorn @viticci @scheemunai @mamuso @RichSilver @TylerNishida @SuddenlyJon @Boilerfan1234 @humanmeteorite @MSaintjour
Hiten Shah @hnshah
What Are People Turning Into Grok Bots? — I looked through 407 public Grok Bots. The jobs people are giving them are getting surprisingly specific.
I’ve been giving Grok Bot a new job every day this week. After building a few, I wanted to see
♥ 69 · ⟲ 5 · 👁 15.6KView on X ↗

Anthropic Open-Sources Claude Commerce Agents Blueprint

Anthropic Open-Sources Claude Commerce Agents Blueprint▶

Anthropic's developer account says it is open-sourcing Claude Commerce Agents, a blueprint for building shopping and merchant agents. Reference implementations cover retail, travel, telecom and entertainment, shown in an accompanying video.

Original post · 1 min read
We're open-sourcing Claude Commerce Agents.

This is a blueprint for building shopping and merchant agents, with reference implementations across retail, travel, telecom, and entertainment.
♥ 11.8K · ⟲ 970 · 👁 2.2MView on X ↗

Open-Source Claude Code Skill Mines Reddit and X for Prompts

Open-Source Claude Code Skill Mines Reddit and X for Prompts

Spencer Baggins describes an open-source MIT-licensed Claude Code skill, /last30days, that scans Reddit and X from the last 30 days on a topic and generates ready-to-use prompts based on community practices. He says it works for tools like Midjourney, Suno and Cursor.

Original post · 1 min read
This feels like cheating.

Someone built a Claude Code skill that scans Reddit and X from the last 30 days on any topic you give it, then writes you copy-paste-ready prompts based on what the community has actually figured out not what was working six months ago.

You type /last30days prompting techniques for ChatGPT for legal questions and it comes back with the top patterns real lawyers and power users are using right now, complete with a fully written prompt you can drop in and use immediately.

No more Googling, no more digging through threads, no more prompts that worked last year but got patched out.

It works for anything - Midjourney techniques, Suno music prompts, Cursor rules, trending rap songs, whatever you need to know what people are actually saying about right now.

100% Open Source. MIT License.

Link in the comments.
♥ 768 · ⟲ 74 · 👁 43.8KView on X ↗

Cursor Plugin Offers Skill-Evaluation Playbook for Pstack

plugins/pstack/skills/poteto-mode/playbooks/eval.md at main · cursor/plugins

Lauren suggests using the poteto-mode skill in Cursor's pstack plugin to update and evaluate a skill, even hill-climbing on it. She links to the eval playbook in the cursor/plugins GitHub repository.

Original post · 1 min read
@petergyang if you have pstack i would suggest using "/poteto-mode update and eval the skill to <change>", you can even hillclimb on it

github.com/cursor/plugins/blob/main/pstack/ski…
github.complugins/pstack/skills/poteto-mode/playbooks/eval.md at main · cursor/pluginsCursor plugin specification and official plugins. Contribute to cursor/plugins development by creating an account on GitHub.
♥ 222 · ⟲ 10 · 👁 19.3KView on X ↗

Shopify Open-Sources Core Infrastructure Behind Self-Improving ML Loops

Shopify Open-Sources Core Infrastructure Behind Self-Improving ML Loops

Tobi Lutke says Shopify open-sourced core infrastructure enabling self-improving training loops, linking to Tangle, a visual ML pipeline editor. He cites a fine-tuned 0.8B model outperforming GPT-5.6-sol xhigh on a specialized task.

Original post · 1 min read
Btw we open sourced the core infra piece that makes these self improving loops possible. tangleml.com
tobi lutke @tobi
Training tiny models for special purpose use cases works so incredibly well if you have a great self improving recursive flywheel. Shopify ML team is on fire.

finetuned 0.8b model beats GPT 5.6-sol xhigh in this very specialized task.
tangleml.comTangle - Visual ML Pipeline Editor | TangleTangle is a system that helps teams build, run and share Machine Learning pipelines visually, without having to set up development environment.
♥ 4.1K · ⟲ 230 · 👁 366.0KView on X ↗

Grok Bot Gains Tinkabot, a Tool That Builds Plugins From APIs

Lauren announces tinkabot v0.1.0, an assistant for Grok @bot that inspects APIs, creates MCPs or skills, and packages them as plugins submittable for approval. Approved plugins become available to all Grok @bot users.

Original post · 1 min read
meet my new grok @bot tinkabot (v0.1.0)! she helps you make high quality grok bot plugins. you can ask her to look at your APIs, create an MCP and/or skills for it, and then wrap that up as a plugin that you can then submit to us for approval.

once it's approved, your plugin will be available for all grok @bot users to use!

let me know if you run into any issues, i've used it on some small toy APIs but would love to see how well it works on real ones

x.ai/bot/br5f3C4mc75QCMEHaszXd
♥ 1.4K · ⟲ 78 · 👁 237.6KView on X ↗

Cloudflare MCP Uses Code Mode to Expose Full API Compactly

Cloudflare MCP Uses Code Mode to Expose Full API Compactly▶

Jilles Soeters demonstrates the Cloudflare MCP, which uses Code Mode to access about 2,500 API endpoints in roughly 1,000 tokens. In a video he buys a domain, deploys a React app, and has an agent fix and redeploy it.

Original post · 1 min read
The Cloudflare API has an incredible MCP. It uses Code Mode so you get access to the entire Cloudflare API (~2500 endpoints) in ~1k tokens.

In this video we use the MCP to buy a domain, deploy a React app to it, have my agent check errors, fix them and re-deploy.

It's SICK🔥
♥ 350 · ⟲ 33 · 👁 26.8KView on X ↗

Open-Source iOS Phone Farm Released Under Apache-2.0 License

GitHub - Git-Agni/prod-FARM-IOS-Core: A farm of real iPhones, run from your Mac. Open-source iOS device automation with live control, a Postgres-backed scheduler, and TikTok workflows. Self-hosted, Apache-2.0.

An Nayal announces an open-source, self-hosted iOS phone farm under Apache-2.0 that lets users register real iPhones, control them live in a browser, and schedule TikTok automation via a Postgres-backed scheduler. Links point to the GitHub repo and setup guide.

Original post · 1 min read
done, it's open source now ✅

iOS phone farm - register real iPhones, watch + control them live in the browser, schedule tiktok on a postgres-backed scheduler.

free, self-hosted, apache-2.0.

- git: github.com/Git-Agni/prod-FARM-IOS-Core
- DIY steps: gethandler.ai/ios-farm/
An Nayal @consumerxai
complete remote controlled iOS phone farm

learning from the chinese friends, building a better version

shall we open source this?
github.comGitHub - Git-Agni/prod-FARM-IOS-Core: A farm of real iPhones, run from your Mac. Open-source iOS device automation with live control, a Postgres-backed scheduler, and TikTok workflows. Self-hosted, Apache-2.0.A farm of real iPhones, run from your Mac. Open-source iOS device automation with live control, a Postgres-backed scheduler, and TikTok workflows. Self-hosted, gethandler.aiiOS Farm - run a farm of real iPhones from your MacOpen source and self-hosted: register real iPhones, watch and control them live in the browser, and schedule TikTok automation. By Handler.
♥ 4.4K · ⟲ 347 · 👁 1.0MView on X ↗

Vercel Pushes Markdown Design Files to Scale Design Taste

Vercel Pushes Markdown Design Files to Scale Design Taste

Guillermo Rauch promotes a Vercel blog post on DESIGN.md, a single Markdown file that encodes design decisions for the company's agents to build on-brand pages, with eval-driven feedback from production.

Original post · 1 min read
Your next design system is… Markdown.

We wrote about how 𝙳𝙴𝚂𝙸𝙶𝙽.𝚖𝚍 is helping solve the hardest problem in AI today: slop.

And how you can truly, finally scale design taste within a large organization.
Vercel @vercel
Our agents use 𝚟𝚎𝚛𝚌𝚎𝚕​.𝚌𝚘𝚖/𝚍𝚎𝚜𝚒𝚐𝚗​.𝚖𝚍 to build on-brand pages.

▪︎ One file encodes decisions and guidance
▪︎ Output is shaped through our eval harness
▪︎ Production feedback is fed back into the loop
vercel.com/blog/how-our-agents-build-on-brand-…
♥ 4.3K · ⟲ 203 · 👁 581.6KView on X ↗

Lauren Begins Guide to Pstack Agent Engineering Workflow

The Complete Guide to pstack Pt. 1

Engineer Lauren, known as @poteto, begins a multi-part guide to pstack, her set of skills for rigorous agent-assisted engineering, claiming it enabled about 2,000 PRs a month. Part one centers on verification skills that let agents check their own work.

Original post · 12 min read
I'm writing a guide to pstack! Here's part one.
X ArticleThe Complete Guide to pstack Pt. 1
In this series of posts, I'm going to show you how I use pstack, my personal set of skills for doing rigorous engineering work. It's allowed me to ship 2,000 PRs a month to production with high confidence.

Personally, I have never put much emphasis into how many lines of code or how many PRs I was landing. Before agents, no one cared, and rightfully so, as raw productivity did not always equate to quality or a visible outcome for users. It was simply a vanity metric.
But I've discovered through the course of building pstack that volume does matter, especially when you are able to maintain or even increase the level of quality of the product with agents. For example, I started working on Grok @Bot about 2 months ago, when it was still in its early days and the codebase was fresh but starting to grow. Despite the team growing and now landing hundreds of PRs a day into the Grok @Bot codebase, pstack has allowed me to keep the quality of the code high for everyone as I constantly monitor code, refactor, add new lints and checks, and also work on features.

Being Grok @Bot's gardener and maintainer is something I was only able to do through pstack. Our early momentum after building the prototype was very high and many people were joining the team. I had a critical moment of opportunity to refactor the whole codebase, while it was being built and extended and with no downtime, into something with strong foundations. A codebase with high quality that scales no matter how many engineers (and most importantly, non-engineers) contribute to it. All of this work requires me to refactor and improve the foundations of Grok Bot as it's being built, and you can only do that when the foundations can keep up with the number of contributions.

The proof is in Grok @Bot itself. Over the next few weeks, I'll tell you everything you need to know to be able to build and maintain a high quality app using pstack.
Part 1 – Verification is all you need
The most critical skill to have in your toolbox is a high quality verification skill. This skill is so important to have and maintain that I think of it more like critical infrastructure rather than "just" a skill. A good one will amplify the output of your whole team, including non-engineers. Done well, you will 100-1000x your whole team's output.
If you're not familiar with the term, verification means that an agent can verify its own work. It can keep going until it succeeds at its task, because it can now close the loop without you being the bottleneck. If you're interested to know more of the story of how I created my first verification skill for Cursor, check out my previous post Loops You Can Trust.
Let's build a verification skill together
To start, install pstack and then run /create-verification-skill. I also recommend adding Dr Eggbot, my bot that helps you create high quality bots, to your roster. Dr Eggbot ships with pstack. It’ll teach coding bots how to use it, and it can also make non-coding bots with the same rigor.
You can ask Dr Eggbot to create an engineer bot for you that you can then ask to run /create-verification-skill and set up a daily routine to run /maintain-verification-skill.

While that runs, let's walk through what the skill does and how it makes a high quality verification skill for you.
I distilled all of our verification skills that we use to build Grok @Bot and Cursor into this skill as a sort of meta-skill. It teaches your agent how to create a high quality one for your own app.
Now this is where choice of tech stack is important. If you're building an app in Electron or for the web for example, you can take advantage of the rich debugging tools available for the JS ecosystem. For example, the Chrome DevTools Protocol (CDP) allows you to use the same tooling available in your browser's developer tools. Or if you're building an iOS app, making use of the simulator.
You ideally want the ability to interact with your app, debug it, take perf traces, and any other debugging and development tooling that you might typically use if you were developing the app by hand. If you don't have a rich runtime to make use of, you may need to ask your agent to create tools for you (eg using lldb, or a custom package that runs as a sidecar in dev environments), or just make use of what you have available.
I personally feel that agentic verification is so important that I would unironically suggest building your own rich debugging tools, or even choosing a different tech stack, in order to have unfair advantages and extreme productivity in building software. As I mentioned earlier, giving agents the ability to verify their own work unlocks everyone in your organization to be able to contribute and validate that their changes actually work. The harder your tech stack is to debug and control, the more difficult it will be to use agents productively.
Make it Reproducible
In pstack, we have a principle called "Build the Lever". What this means in the context of c… continue on X ↗
♥ 7.1K · ⟲ 648 · 👁 1.2MView on X ↗

Luke Wroblewski Open Sources Rebuilt Intent for Agent Coordination

Luke Wroblewski Open Sources Rebuilt Intent for Agent Coordination

Luke Wroblewski announces a complete rebuild of Intent, an open-source tool for coordinating large numbers of agents, arguing chat-era apps were not designed for software development with hundreds of agents.

Original post · 1 min read
software development today is building with 100s of agents. chat-era apps weren't designed for that scale. so we rebuilt Intent completely and open sourced it with a venerable dream team of talent.
intentapp.dev/
intentapp.devIntentBuild with Intent. Large-scale agent coordination for developers.
♥ 138 · ⟲ 18 · 👁 47.0KView on X ↗

Uber Details Software Factory Cost Model Across Agent Layers

Running a Software Factory Efficiently at Uber Scale

Uber Engineering publishes an article by Uday Kiran on its software factory, reporting over 70% of pull requests attributed to agents, 3,600 agent skills, and a cost equation showing cost per 1,000 requests down about 34% from peak.

Original post · 12 min read
X ArticleRunning a Software Factory Efficiently at Uber Scale
Post author: @udaykiran

Introduction
AI tools are now embedded in every phase of software development at Uber. More than 70% of pull requests are attributed to local or cloud agents. Engineers have built over 3,600 agent skills across the software development life cycle, and executed more than 30K agent skill executions per day.
At the AI Engineer 2026 conference, we shared our vision for the Software Factory and the building blocks and managed agents we are building across the lifecycle. As we progress on that vision, a growing share of sessions aren’t initiated by humans, but by automated managed agents handling code review, self-healing CI failures, completing E2E PRs with visual validation, triaging on-call alerts, debugging incoming bugs, and handling a variety of code maintenance tasks with human reviews/escalations.
As shown in Figure 1, from February to Aug 2026, weekly active users across all agentic offerings across all our employees (engineers & non-engineers) grew 7x, and weekly agentic requests grew 9.4x. Meanwhile, our total AI spend has relatively stabilized since April due to optimizations across the board.

Since adoption, workload mix, and model upgrades are all continuously changing, isolating our own optimization gains means holding one model fixed, since behavior shifts with every upgrade and model family. We did that from February to July: cost per 1,000 model requests is down almost 34% from its peak, and cost per session is down 52% from its June peak.

This blog walks through how we think about our software factory: the four layers agent sessions run in, the cost equation we use to decompose spend, how we measure each term, and how we optimize those terms across every layer.
All pricing and vendor metrics in this comparison are based on publicly available information, with cost efficiency gains driven by routing our internal Uber workloads more intelligently within standard tier-pricing. While specific cost reductions we measure are unique to our environment and your mileage may vary depending on your codebase, team size, and agent workflows, the methodology of benchmarking real work and optimizing for accuracy and cost is universally applicable.
The Software Factory and Its Cost Equation
Four Layers of Agent Usage
We organize AI usage into four layers, from the most specialized to the most general. As shown in Figure 3, the higher the layer, the more control we have over cost, quality, and model selection.

The Cost Equation
Across any of the layers above, we can decompose the cost of an agentic session into the following terms, which we could measure and optimize independently.

The first two terms represent adoption & engagement, which we want to keep growing across our overall user base, whether users use it interactively or agents handle tasks on their behalf. The three middle terms provide opportunities for optimization: the work the agent does on its own behalf, on top of the request an engineer actually made. That is where most of our effort goes. This includes mechanisms that help agents plan faster, reduce unwanted turns or errors, optimize input tokens, and more.
How We Measure
Below is the full set of metrics we track weekly and monthly that enable us to forecast & plan our efforts short-term and long-term.

Optimization Levers
In the following sections, we detail the key levers we used to optimize each part of the cost equation. Some of these levers affect one or more rows in the cost equation.

Optimizing Price / Token
The vendor sets the token price. We pick which model runs which workload. Across all our managed agents’ layers, we pick the model that’s most Pareto efficient for that workload. For us, Pareto efficient means cost/completed task, output quality, and model reliability.
Benchmark-Driven Model Selection
Model selection happens in four steps, the same for every managed agent we run.
Build a benchmark out of the agent’s real work.
Run the agent on a harness that serves any model, frontier or open-weight, behind one interface.
Move to whatever is Pareto optimal, and keep moving. The frontier shifts every few weeks.
Looking ahead, we continually refine our workload performance by leveraging aggregated insights from our managed agents to test and deploy various model routing strategies.
For example, we use uReview, which handles AI code review for all pull requests. We built its benchmark from real pull requests with known bugs and graded them easy, medium, and hard. We score precision, recall, and F1 against those bugs, plus cost per review, latency, timeouts, and noise. As shown in Figure 5, switching models improved our F1 while dramatically reducing cost/PR. In the figure, the dashed line is the Pareto frontier. Everything below and left of it is beaten by something cheaper or better.

Using thousands of real-world PRs across our large monorepos, we internally also have an Uber SWE Benchmark that runs frontier and open-weight models across differe… continue on X ↗
♥ 4.8K · ⟲ 777 · 👁 2.7MView on X ↗

Bezalel Offers One MCP Giving Agents Computer, Email and Memory Access

Micky introduces Bezalel, a free alpha capability plane that gives agents such as Claude and Codex computer, sandbox, iMessage, email, memory and connector access through a single MCP, built on services from Orgo, Vercel, Composio and others.

Original post · 1 min read
For everyone asking,

> computer: @orgo
> sandbox: @vercel
> cards: @agentcardhq
> email: @agentmail
> imessage: @PhotonHQ
> memory: @supermemory
> connectors: @composio

With one MCP you can give your agents access to all of the above... free for some time

Enjoy bezalel.sh
Micky @Rasmic
Meet Bezalel

Bezalel is a capability plane for your agents (claude, codex, OC, hermes, etc)

one MCP gives your agent:
💻 computer
⌛️ sandbox
🍎chat via iMessage
📧agent's own email
+1k connectors
🧠memory
💳 a card (soon)

bezalel.sh/ (it's in alpha and it's free)
♥ 644 · ⟲ 43 · 👁 95.2KView on X ↗