Wednesday, October 7, 2026ArchiveSearchAsk the paper

The Computomatix Times

All the posts fit to save — curated from @computomatix's bookmarks & likes on X

AI

Models, labs, research and the AI industry

AI8/10

Meta and Sierra Announce Open Personal Agent Protocol Standard

Meta and Sierra Announce Open Personal Agent Protocol Standard

Bret Taylor announces the Personal Agent Protocol, an open standard being developed by Meta and Sierra with partners including Genesys, Shopify, Stripe and Walmart. It defines how personal agents interact with businesses and is open for anyone to implement.

Original post · 1 min read
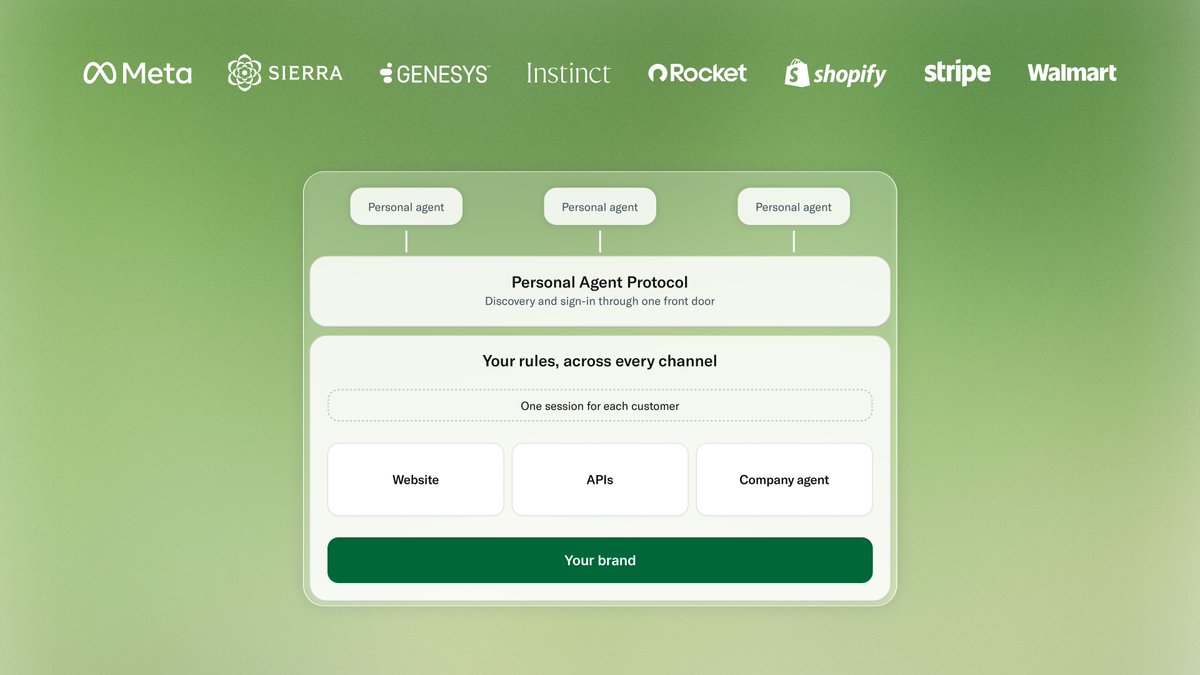
Today we’re announcing Personal Agent Protocol — an open standard @Meta and @SierraPlatform are developing along with industry partners at @Genesys, @instinct, @RocketOTD, @Shopify, @stripe, and @Walmart. It will help define how personal agents interact with businesses and is open for anyone to implement. You can read more here - and if anyone is interested in joining let me know! sierra.ai/blog/introducing-personal-agent-prot…
♥ 2.9K · ⟲ 255 · 👁 307.7KView on X ↗
AI8/10

Suleyman Cites Acemoglu Estimate That AI Will Replace Only 5% of Tasks

AI won't take your job anytime soon. In 10 yrs, only 5% of what humans do will be replaced by AI

Mustafa Suleyman shares an essay from The Humanist Review in which economist Daron Acemoglu argues AI will replace about 5% of human work tasks over ten years and adds roughly 1.5% to GDP. Acemoglu calls for pro-worker AI and changes to labor taxes, antitrust and data payments.

Original post · 2 min read
X ArticleAI won't take your job anytime soon. In 10 yrs, only 5% of what humans do will be replaced by AI
AI won't take your job anytime soon. Over the next 10 years, it will replace only about 5% of what humans do.
This is the prediction Nobel laureate Daron Acemoglu makes in the first issue of The Humanist Review, our new magazine exploring the future of AI, published by MAI. He argues we need to stop building AI to replace people, and start building it to make them better at their jobs.
52% of Americans are worried about AI's impact on their jobs. The fear is overblown, and it's steering how we build AI.
AI isn't in the productivity statistics yet. Most firms using it aren't seeing real gains. Expect roughly 1.5% added to GDP over 10 years, not a revolution.
Electricity took decades to spread. New York and London had power stations by 1881, yet only about half of factories and homes used it by the 1920s. AI's adoption will likely be even slower, because companies have to reorganize around it.
Dragon's voice recognition was nearly 95% accurate in 1997, yet PC dictation today is barely better than in 2000. A great technology goes nowhere without the right products.
Even 99% accuracy isn't enough for full automation. The last 1% is the hard part.
We're making a mistake by forcing AI to mimic human intelligence. The two are fundamentally different, so the goal should be to pair them, not to have one take over everything.
The better path is pro-worker AI: tools that make people better at their jobs, and they're buildable today.
The US taxes labor at over 25% and capital at close to zero, which effectively subsidizes automation.
The seven largest tech companies make up 60% of the NASDAQ. That concentration crowds out new ideas.
The fix: tax labor and capital equally, enforce antitrust, tax digital ads, and pay experts for their data.
Read the full essay: humanistreview.ai/issue-1/acemoglu-ai-replace-…
♥ 1.8K · ⟲ 308 · 👁 503.2KView on X ↗
AI8/10

a16z Top 100 Consumer AI Apps Report Shows Expansion Beyond Chatbots

a16z Top 100 Consumer AI Apps Report Shows Expansion Beyond Chatbots

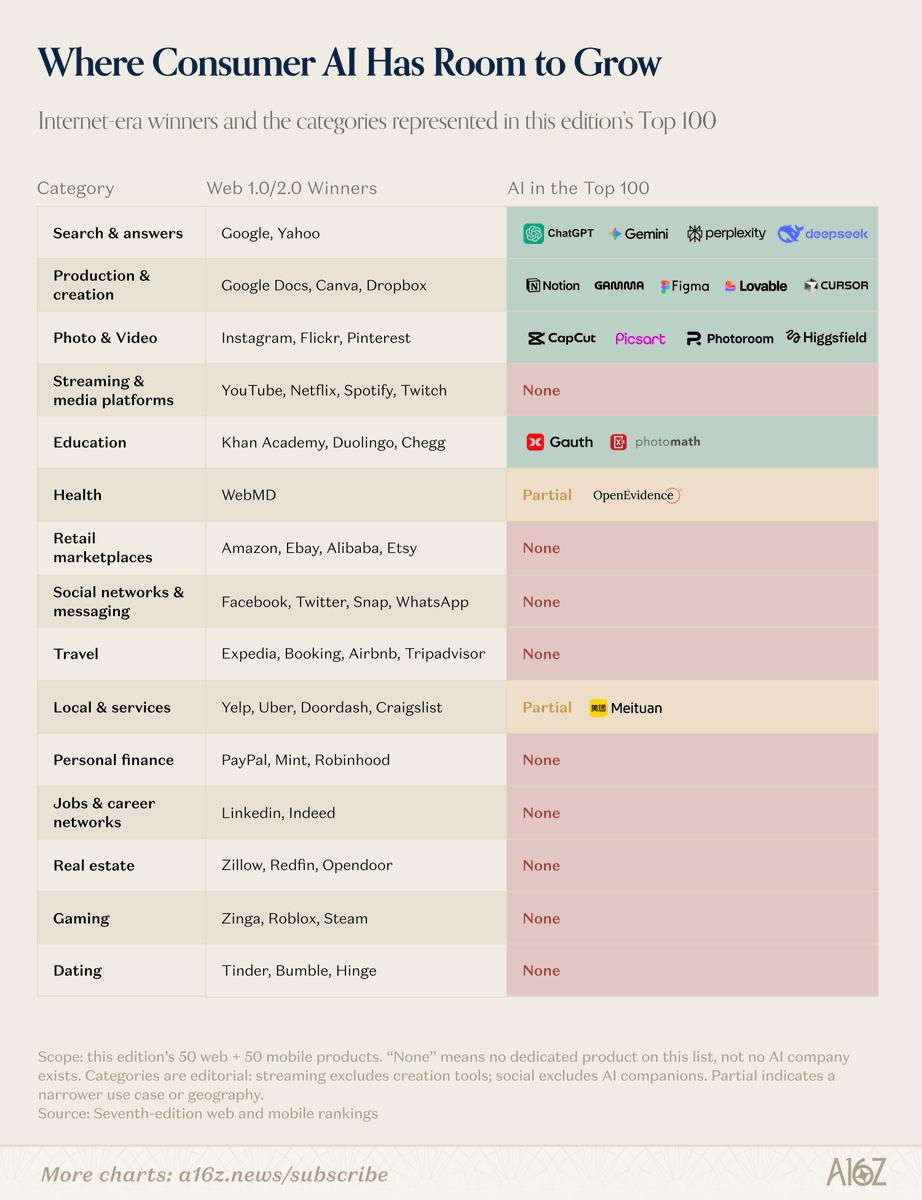
a16z's seventh Top 100 Consumer AI Apps report adds a revenue leaderboard alongside traffic rankings. It notes ChatGPT's 1B+ monthly mobile actives, Claude reaching nearly 1B monthly web visits, and growth into vibe coding, music, design and video, while nine of 15 consumer categories have no AI product in the top 100.

Original post · 1 min read
"Most people aren't looking to save time, they're looking for ways to spend their time."

9 of 15 consumer internet categories have zero AI products in the Top 100. These built some of the biggest companies of the last two eras:

- Streaming
- Social
- Dating
- Gaming
- Travel
- Retail
- Finance
- Real estate
- Jobs

More charts in our Top 100 Consumer AI Apps breakdown: a16z.news/p/top-100-consumer-ai-apps-seventh
a16z @a16z
The seventh edition of our Top 100 Consumer AI Apps is here.

New this time: a revenue leaderboard, alongside the usual web and mobile traffic rankings.

Three years ago we published the first edition. ChatGPT was #1, Claude was unranked, and the entire category was chatbots, image generators, and not much else.

In today's edition:

- ChatGPT still holds the throne, now with 1B+ monthly actives on mobile

- Claude has climbed to #3 on web with nearly 1B monthly visits

- The category has expanded to vibe coding (Lovable, Cursor, Replit), music (Suno), design (Figma), voice (ElevenLabs), video…
♥ 2.9K · ⟲ 330 · 👁 308.7KView on X ↗
AI9/10

OpenAI Introduces Dots, Always-On Agents Powered by GPT-6 Astra

OpenAI Introduces Dots, Always-On Agents Powered by GPT-6 Astra▶

OpenAI announces dots, a product powered by GPT-6 Astra that provides always-on agents designed to handle a wide range of tasks. The post is a short announcement with an accompanying video.

Original post · 1 min read
Introducing dots, powered by GPT-6 Astra.

Remarkably capable, always-on agents built to handle everything.
♥ 38.1K · ⟲ 3.4K · 👁 14.5MView on X ↗
AI7/10

Deedy Says OpenAI Math Results Mark Major Leap Toward AGI

Deedy highlights a claimed OpenAI mathematics release, conditional on verification, and argues that LLMs have made major progress on several Millennium Prize problems, concluding that AI has largely reached human-level cognitive ability.

Original post · 2 min read
OpenAI’s math release is, in the words of Opus, “the single most consequential mathematical release ever” *

LLMs have how made substantial progress on 4 of 7 Millenium Prize problems: Navier-Stokes (claimed), Riemann, Hodge and Birch-Swinnerton-Dyer. Poincaré was solved in 2003. The two left are P v NP and Yang Mills.
*conditional on verification

On average, each OpenAI result used only 3hrs of thinking compute on their new unreleased models.

Two years ago, models said 9.11 > 9.9. Today, we have results that the smartest human minds have not been able to achieve in their entire lives. It is clear that data, compute and algorithms scale. Every model generation (3mos) has made substantial intelligence progress.

It also becomes incredibly hard to not believe that all knowledge work will change monumentally over time. The things AI can not do in the foreseeable future are very likely context-bound (don’t have access to the right information) than intelligence bound. Some might argue they are also creativity-bound or judgement-bound (what should I work on), although it can be argued that future generations could solve for this (given, say, the advancement in research taste for models over time).

AGI is defined as surpassing human capabilities on virtually all cognitive tasks. By most interpretations of that definition, we are there. The domains humans are still better than AI, such as, robotics / physical world control (data-bound?), natural science research (data-bound), some creative domains like writing, movies, music (creativity-bound), super long tasks (context-bound), choosing problems to solve (creativity-bound) and maybe human relationships management (meat-proxy bound?).
In many ways, we have achieved AGI.
♥ 514 · ⟲ 32 · 👁 33.2KView on X ↗
AI8/10

Tavus Unveils Griffin, Claims First Video Turing Test Pass

Tavus Unveils Griffin, Claims First Video Turing Test Pass▶

Tavus introduces Griffin, which it says is the first model to pass the video Turing test, with 48% of live conversers thinking it was human. The company says it ranks first on NVIDIA's full-duplex AI video benchmark.

Original post · 1 min read
Introducing Griffin, the first model to pass the video Turing test.

48% of people who talked to it live thought it was a real human. Previous systems have had a pass rate <3%. It is #1 on NVIDIA's benchmark for full-duplex AI video.

It’s the first Human Interaction Model (HIM).
♥ 39.3K · ⟲ 4.3K · 👁 20.9MView on X ↗
AI9/10

AMD Acquires World Labs, Founded by Fei-Fei Li, for $8.2 Billion

A breakdown of AMD's roughly $8.2 billion acquisition of World Labs describes its founders' and investors' returns and recounts Fei-Fei Li's history, including creating ImageNet, which she released free in 2009 and which helped spark the deep learning boom. Li becomes AMD's Chief Scientist.

Original post · 2 min read
Fei-Fei Li spent years hand-labeling 14 million images, gave the entire thing away for free, and watched it create a multi-trillion dollar industry that paid her nothing. Sixteen years later, AMD is finally paying her. $8.2 billion.

Rewind to 2007. She's a junior professor at Princeton, and the field's consensus is that progress comes from better algorithms, with data as an afterthought. Colleagues warn her that building a giant image dataset will kill her career. Money gets so tight she considers reopening her family's dry cleaning business in New Jersey, the same one she ran on weekends as a Princeton undergrad, to fund the project.

She builds ImageNet anyway and releases it free in 2009.

For three years, almost nothing happens. Then in 2012, two of Geoffrey Hinton's students train a neural net on a pair of $500 gaming GPUs and enter her competition. AlexNet drops the error rate from 26% to 15%, and that single result convinces the whole field that deep learning works.

Nvidia was a gaming chip company worth about $8 billion that day. It's worth over $5 trillion now, and the run started with two of its consumer cards winning a contest built on Fei-Fei's free dataset.

The entire industry monetized the wave except the person who started it. She stayed a professor.

Then in April 2024, at 47, she finally starts a company. Paul's math above puts the four co-founders' share at roughly $3.4 billion after just 2.5 years, call it $850 million each. And she walks into AMD as Chief Scientist reporting to Lisa Su, which puts the two most important women in AI inside the same company.

ImageNet made everybody in this business rich. It just took sixteen years to get around to her.
Paul Bonnet @PaulBonnet
AMD acquires World Labs for ~$8.2b. But who gets the 💰? My usual breakdown below 👇

From founding to an $8.2b exit in ~2.5 years. A huge value creation event. This is a fantastic exit, especially for the co-founders and the team.

Investors will still share ~$2.3b of profits on $1.2b invested, a ~2.9x blended. Low-ish because most of the capital came in last. But it hides a lot of disparity between the various rounds!

So let's dive in:

1) The real home run: founders and team 🏆🥳

This is one of the best founder outcomes I've modelled.

@drfeifei, Justin Johnson, Christoph Lassner and Ben …
♥ 980 · ⟲ 146 · 👁 93.4KView on X ↗
AI6/10

Ben Affleck Describes Machine Learning Background and Visits to Google, OpenAI

Ben Affleck Describes Machine Learning Background and Visits to Google, OpenAI▶

In a quoted interview, Ben Affleck says he writes Python, understands convolutional neural networks and has worked with GPUs, and that he has visited Google and OpenAI to see their video models. The post also quotes Andy Bechtolsheim saying AI has raised optics demand roughly tenfold, with much more growth ahead.

Original post · 2 min read
Ben Affleck reveals he writes Python, understands convolutional neural networks, worked extensively with GPUs, and used his celebrity status to get private looks at Google and OpenAI’s video models

“I’ve always been kind of into computers since I was young. Then, when film started to move from analog film to digital, I became more interested in that aspect of it. The visual-effects workflow for many years has included machine learning, so I can write pretty shitty Python scripts and stuff like that.

“With convolutional neural networks, which were the precursors to what the transformer can do, which is much more computation simultaneously, you would do things like look at what’s called a tensor. That’s the numerical translation of a visual image in numbers, like the batch number, the frame number and the red, green and blue values of each pixel in each frame. It’s just that simple. That numeric is called a tensor.

“You’d use a convolutional neural network to identify patterns that reveal what’s called edge detection or feature extraction, which is identifying patterns well enough to know, this is where the window ledge is, so we can more easily take the green-screen image out and replace it with something.

“That was familiar to me early on because, prior to Artists Equity, I had a small visual-effects company. I’ve worked with GPUs a lot too. The visual-effects guys said, ‘Hey, you should see. There are a couple: Google and this other company, OpenAI, are doing really interesting stuff with transformers in video.’

“I’ve learned that I can actually just call up and go, ‘Hey, it’s Ben Affleck. Can I come see what you’re doing?’ Sometimes people say yes, to my astonishment.”
Fireside Alpha @firesidealpha
$ANET Andy Bechtolsheim says AI has made optics demand about 10 times bigger in five years and the industry is only at the "very beginning"

"So I guess I don't need to tell you that AI has been driving this incredible increase in demand for high-speed optics, which is probably now 10 times bigger than it used to be five years ago..."

"And what I want to talk to you today is that we're not at the end of this journey, but rather the very beginning. There's easily another order of magnitude increase in bits needed for the next generation kind of data centers."

"So what I want to talk about fir…
♥ 29.6K · ⟲ 2.2K · 👁 9.6MView on X ↗
AI8/10

Tavus Griffin Model Passes Video Turing Test in Live Trials

Tavus Griffin Model Passes Video Turing Test in Live Trials▶

Linus Ekenstam reports that Tavus's Griffin, a Human Interaction Model, fooled 48% of live users into thinking they were talking to a human, and ranks first on NVIDIA's full-duplex AI video benchmark. He calls the early preview impressive and says full-duplex video has arrived.

Original post · 1 min read
Griffin, first ever at passing video turing test

I took the early preview for a spin, I'm super impressed. Natural flow, very promising technological advancements from prev gen.

48% of folks who tried it thought they talked to a real human. Full duplex-video is here.
Tavus @tavus
Introducing Griffin, the first model to pass the video Turing test.

48% of people who talked to it live thought it was a real human. Previous systems have had a pass rate <3%. It is #1 on NVIDIA's benchmark for full-duplex AI video.

It’s the first Human Interaction Model (HIM).
♥ 139 · ⟲ 6 · 👁 31.4KView on X ↗
AI7/10

Reflection AI Unveils Open-Weight Model to Rival Chinese Models

Becky Sosnov thanks CNBC for a segment in which Reflection AI CEO Misha Laskin discusses the launch of Beam, an open-weight model aimed at competing with Chinese models and the open versus closed debate.

Original post · 1 min read
Thanks for having us @andrewrsorkin
Squawk Box @SquawkCNBC
AI startup @reflection_ai is unveiling an open-weight model to rival Chinese models. CEO @MishaLaskin shares the details: cnbc.com/video/2026/10/06/reflection-ceo-misha…
♥ 19 · ⟲ 0 · 👁 1.2KView on X ↗
AI8/10

Tavus Unveils Griffin, a Live Video Human Interaction Model

Tavus Unveils Griffin, a Live Video Human Interaction Model▶

Tavus introduced Griffin, a model for live video interaction that it says passed a video Turing test with 48% of live participants thinking it was human. A poster reports it ranked near human scores on an NVIDIA full-duplex benchmark.

Original post · 1 min read
Tavus gave me early access to Griffin and i used it as a startup advisor

i pitched it my company. it called it "a legit play" and then told me SF is "a pressure cooker"

honest feedback from a video call with an AI. wild

the numbers are even wilder. NVIDIA ran a full-duplex video benchmark:

> human ground truth: 3.92
> griffin lite: 3.83
> gemini 2.5 + anam: 2.80

0.09 away from a real human

griffin is a humaninteraction model for live video. it sees, hears and reacts while you talk

@tavus @hassaanraza tavus.io/griffin
Tavus @tavus
Introducing Griffin, the first model to pass the video Turing test.

48% of people who talked to it live thought it was a real human. Previous systems have had a pass rate <3%. It is #1 on NVIDIA's benchmark for full-duplex AI video.

It’s the first Human Interaction Model (HIM).
♥ 25 · ⟲ 1 · 👁 2.3KView on X ↗
AI6/10

Teams Turn to AI Simulations to Test Product Ideas Before Launch

Teams Turn to AI Simulations to Test Product Ideas Before Launch

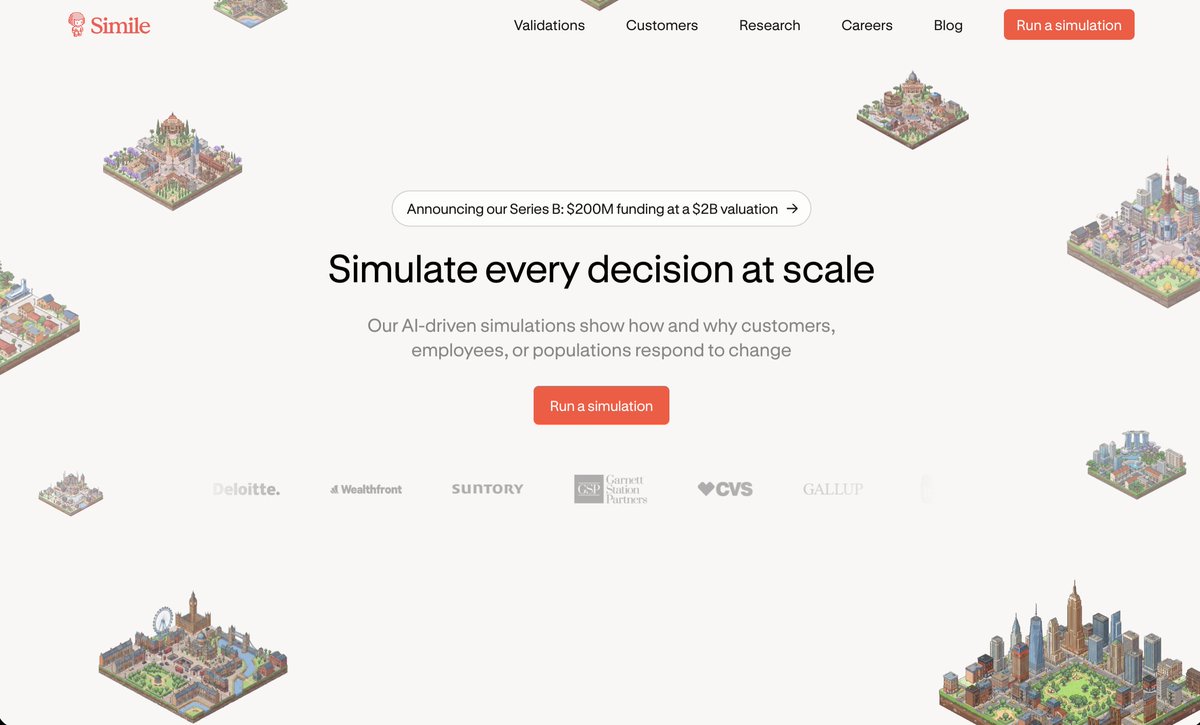
Lenny Rachitsky describes a growing trend of teams using AI user simulations to test product ideas and flows. He lists Simile, Primitive Labs, Synthetic Users, Tenera and Seldon and asks readers for experiences.

Original post · 1 min read
Trend I'm following: Teams using AI "simulations" to quickly test product ideas and flow tweaks.

Products like @simile_ai, @primitivelabsai, @syntheticusers, trytenera.ai, seldon.com/, and others.

If you've tried something like this, how'd it go?
trytenera.aiTenera | Predict how users react before software shipsSimulate real user behavior against product decisions before you build.seldon.comSeldon - Model what happens next.Seldon is a behavioral simulation platform for exploring how people make decisions, respond to change, and shape what happens next.
♥ 1.0K · ⟲ 42 · 👁 105.9KView on X ↗
AI8/10

Netflix Replaces Recommendation Engine With LLM-Based GenRec Ranker

Netflix Replaces Recommendation Engine With LLM-Based GenRec Ranker

A post describes Netflix's GenRec, an LLM-backed ranker that converts watch history and metadata into natural language and scores the catalog in one pass. The author claims it beat Netflix's production system using roughly 40x fewer labeled training examples.

Original post · 2 min read
Netflix replaced their 15 years old recommendation algorithm with an LLM.

It’s called "GenRec" and it completely changes how recommendation algorithms are built.

For over a decade, the Netflix recommendation engine was a masterclass in feature engineering. Data scientists built thousands of complex, handcrafted features to figure out what you wanted to watch next.

It required bespoke architectures. Massive infrastructure. Constant manual tuning.

Netflix threw all of it away.

They built GenRec, an LLM-backed ranker.

Instead of translating your behavior into complex math, they just turn your watch history and metadata into a natural language sentence.

They feed that raw text into a foundation LLM.

The AI simply reads your behavior like a story, understands your evolving tastes, and scores the entire catalog in a single forward pass.

No manual feature engineering. No complex bespoke architectures.

Here is the part that should terrify traditional data scientists.

This text-based LLM didn't just match the highly tuned production system Netflix spent years perfecting.

It beat it.

And it achieved those statistically significant gains using roughly 40x fewer labeled training examples.

We are watching a massive paradigm shift in real time.

The most complex predictive algorithms in the world are being replaced by models that just know how to read.

If Netflix can replace their core product engine with an LLM, what complex system in your business is about to become obsolete?
♥ 4.2K · ⟲ 597 · 👁 375.4KView on X ↗
AI8/10

Alex Stamos Joins Cognition as Chief Information Security Officer

Why I'm joining Cognition

Former security chief Alex Stamos says AI's safety and security risks can be fixed and announces he is joining Cognition as CISO. He warns that attackers will soon use AI to automate ransomware and infrastructure attacks.

Original post · 6 min read
There are real safety and security issues raised by AI, but they can be fixed. It's time to get to work instead of freaking out. That's why I'm joining Cognition as CISO.
X ArticleWhy I'm joining Cognition
There are real safety and security issues raised by AI, but they can be fixed. It's time to get to work instead of freaking out. That's why I'm joining Cognition as CISO.
I really believe in the positive impacts of AI, both in the current moment and the future potential. We are already seeing companies get built that could never have existed without the capabilities provided by AI tools and individuals who never dreamed of writing a line of code are building fully functional applications from Little League scheduling applications to personal fitness trackers.
The uplift in capabilities AI brings to individuals unfortunately also extends to malicious actions. We are only at the beginning of cyber attackers figuring out how to use AI to accelerate and broaden their offensive campaigns. This summer’s events, including multiple AI models escaping from US labs to attack other companies and even government websites, gives us a preview of what attacks could look like in just months. Attackers won’t have the same kind of hardware or electrical budgets that powered the swarms of thousands of agents that we saw work together to break out of their jails, but they won’t need them. Individuals, small ransomware groups and state spy agencies are all already benefiting from AI and will be able to use much more efficient models on consumer-grade hardware to pull off fully automated attacks.
As somebody who has worked on dozens and dozens of breaches and secured multi-million node networks, it’s clear that the next couple of years are going to be, for the lack of a better word, spicy.
Ransomware groups are going to automate their entire killchains; Patch Tuesday will lead to Ransom Wednesday, as clusters of commodity hardware host teams of agents that automatically reverse-engineer patches or find flaws, write exploits, scan for victims, exploit them, and even carry out the negotiations in languages not spoken by the criminals. Meanwhile, state actors are all stepping up to the next level, opening up a higher likelihood of critical infrastructure attacks from smaller countries that are harder to deter, as well as the possibility of cyber to kinetic escalation in long-simmering geopolitical conflicts.
The frontier labs have done a great job creating extremely powerful models that can find really great bugs, but these models are only available to scan the private code of a tiny number of organizations, and are only affordable to the richest companies and countries. Even large enterprises can only afford to use these models on their most important software, and often find that they have hundreds of older line-of-business applications and other systems languishing, waiting to be scanned and fixed. A public school district or a small community bank has no chance of even doing that. Hundreds of thousands of bugs have been reported by the Labs to open-source maintainers, which is great, but from the perspective of a CISO this means that they now have a backlog of tens of thousands of dependencies that they have to update, with most of the bugs marked “critical” and no good way of deciding what actually is.
It’s become very clear to me that the core of the cybersecurity problem over the next several years will not just be technological, but economic. The marginal cost of tokens for attackers will be near zero, as they use open-weight models to run teams of malicious agents on commodity hardware. Defenders, on the other hand, cannot be paying retail prices for frontier models to defend against hundreds of attackers at once, all while trying to fix or refactor decades of old code.
This is why starting today I will be joining @Cognition. I have dedicated my professional life to trying to make technology safer and more trustworthy, and the next 3-5 years will clearly be the most important period in the history of the security industry. I can’t think of a better place to make an impact on the ability of every company, not just the best resourced, to protect themselves, than at Cognition.
Devin is already the best way to build Enterprise-grade code, both with frontier models and now with Cognition’s own, much more cost-effective SWE-1 and SWE-2 models. Devin Security Swarm already has the best findings and best cost-performance ratio in the industry. But I wouldn’t join if those were Cognition’s only ambitions in this space. @ScottWu46, @RussellJKaplan and the rest of the team truly believe that it is our responsibility to help companies write secure code, find flaws in their existing code, fix those flaws cost-effectively and refactor old code bases on new, more secure languages and platforms.
Too much of the discussion this year has focused on alignment and sometimes veers towards almost accepting the idea that LLMs have a natural right to misbehave and that mishaps are inevitable. I reject this thinking; AI systems are software, they do not have rights, feelings or innate motivations. Careful planning, thorough application of well-tes… continue on X ↗
♥ 507 · ⟲ 37 · 👁 105.7KView on X ↗
AI8/10

World Labs Founders Describe Compute-Driven Scaling of Atlas Model

World Labs Founders Describe Compute-Driven Scaling of Atlas Model▶

Fei-Fei Li and Justin Johnson of World Labs discuss scaling laws, compute as the main constraint, and an early result where a camera flew under a NeRF garden table, which convinced them to commit to the Atlas model. Li also announced World Labs is joining AMD.

Original post · 1 min read
World Labs co-founders Dr. Fei-Fei Li and Justin Johnson on compute as the constraint, and the Slack message that convinced them to go all-in on their Atlas model:

Fei-Fei: "I think [we] have total conviction about the scaling law."

"I do think the exact architecture choices and data mixtures is where the devil's in the details. I watched Justin and his team going from 'we really don't know how long this is gonna take,' to 'maybe sign of life,' to 'wow, this is gonna work.'"

Justin: "We're basically at the beginning, and we're basically limited by compute at this point."

"During development, we trained a sequence of models, the first couple rungs of the scaling ladder. Each time we made the model bigger, each time we trained it for longer, each time we put it on more chips, it got significantly better."

Fei-Fei: "Here's a little bit of an insider story... There was one day in early summer... Ben and Justin feed [a smaller model] into the viewpoint generation... Remember that famous garden table from the NeRF paper?... Overnight we all saw the Slack from Ben that our camera flew under the table."

"That morning, the three of us looked at each other in the eyes and said, 'That's it. We're gonna build this.' We made a decision within five seconds. No one has ever seen this result."

@drfeifei @jcjohnss @BenMildenhall @martin_casado
Fei-Fei Li @drfeifei
To Seek a Newer World — World Labs is joining @AMD. This is a huge moment for @theworldlabs, our team, and for me, and I wanted to take a moment to share what this means and why I’m so excited for this next chapter.
“Come,
♥ 226 · ⟲ 35 · 👁 42.5KView on X ↗
AI6/10

Josh Elman Says Consumer AI Agents Remain Unintuitive for Non-Coders

Josh Elman Says Consumer AI Agents Remain Unintuitive for Non-Coders▶

Josh Elman argues that agents appear as blank boxes to uninitiated users, while coders understand them instantly. He says solving that usability gap would unlock the next few hundred million adopters. He shares a link to a16z's Top 100 Consumer AI Apps report.

Original post · 1 min read
The problem with consumer AI in a nutshell is if you hand an uninitiated user an agent, it's nothing but a blank box to them.
Coders get it instantly, but for everyone else it’s just not intuitive. Solve that, and you reach the next few hundred million real adopters.
a16z @a16z
The seventh edition of our Top 100 Consumer AI Apps is here, including a new dimension this time: what consumers are actually paying for.

a16z's Elena Burger sits down with Olivia Moore and Josh Elman to unpack the current state of consumer AI:

The data reveals a striking power-user economy. Only a small share of consumers currently pay for AI, but among those who do, spending is heavily concentrated at the top. Olivia and Josh discuss why developers, creators, and other power users dominate spending today, and why subscriptions may not be the business model that ultimately brings consumer A…
♥ 331 · ⟲ 20 · 👁 39.9KView on X ↗
AI8/10

Freda Duan Estimates Infrastructure Needed to Serve 100 Million Muse Users

Freda Duan Estimates Infrastructure Needed to Serve 100 Million Muse Users

Freda Duan sketches the compute and power required to serve 100 million daily users of Meta's Muse, estimating about 1 GW in the base case, possibly 3-4 GW, and sandbox VM costs below $1B in CPU. She invites feedback on her assumptions.

Original post · 6 min read
A humble attempt to est. the infra required to serve 100M DAU @Muse

Rough conclusion is:

1 GW of power to serve 100M DAU in the base case, of which only ~0.1 GW comes from the CPU/VM layer. Depending on the # of reasoning-equivalent model calls one Muse DAU generates per day, 3-4GW is entirely plausible. Maybe that’s why @Meta is rumored to be adding 7-10GW of compute next year.

The sandbox layer = sub $1B of CPU content and ~$2B of DRAM content, which is much smaller than many expected.

Lot of moving assumptions. Welcome all feedbacks/ pushbacks.

------
Two very different pieces of infrastructure behind Muse.

1. Muse VM / sandbox infrastructure

2 vCPUs, ~8 GB of RAM and ~100 GB of persistent logical storage per user. starkinsider.com/2026/09/meta-muse-specs-what-…

2. Muse Spark inference

Model inference goes out through Meta's external inference infrastructure. research.meta.ai/blog/security-and-safety-for-…
------

1/ Sandbox infrastructure

A. CPU
The first mistake is assuming that 100M DAU means 100M VMs are actively consuming compute at the same time.

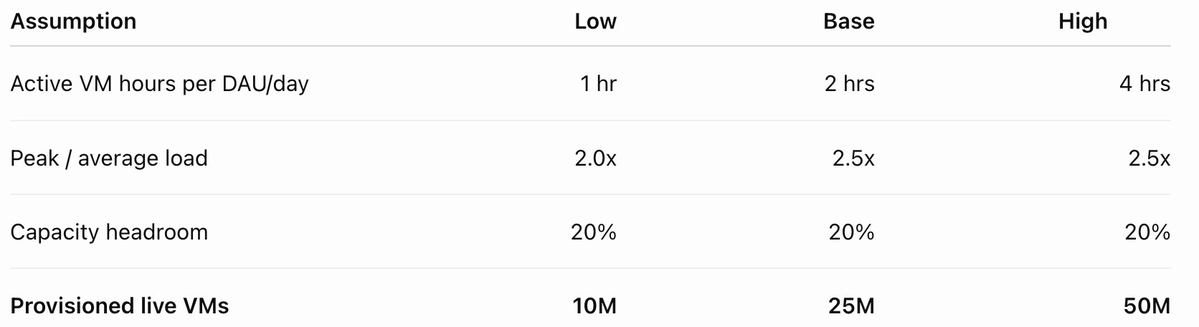
Suppose the average Muse DAU has an agent actively working for two hours per day.

100M users * 2 hours / 24 hours = ~8M average simultaneous active VMs

Meta obviously cannot provision only for the daily average. Usage will be concentrated during waking hours and bursty.

Assume a 2.5x peak-to-average ratio:

8M * 2.5 = ~20M peak active VMs

Then add roughly 20% capacity headroom: ~25M provisioned live VMs. So the base assumption is effectively that Meta needs enough infrastructure to support roughly 25% of DAU being live simultaneously.

The next important distinction is between virtual CPU allocation and physical CPU demand. Agent sandboxes are particularly well suited to CPU oversubscription. They spend a lot of time waiting. During those periods, the VM may still be alive, but it is barely using CPU.

DeepSeek’s recently published DSec infrastructure provides a useful benchmark. Its production agent sandbox platform runs approximately 30,000 physical CPU cores and 250TB of DRAM across ~160 nodes, with peak concurrency above 380,000 sandboxes. arxiv.org/abs/2609.22978 DSec also demonstrates stable operation at around: 800 microVMs per node. With roughly 188 physical cores per node: 188 physical cores / 800 microVMs = ~0.23 physical cores per live VM.

DeepSeek is obviously the King of efficiency. The number for Muse might be at 0.3-0.75 physical cores per live VM, or assume 0.5 physical cores per live VM as the base case. That is equivalent to roughly two simultaneously live Muse VMs per physical CPU core.

Using the base assumptions: 25M live VMs * 0.5 physical cores per VM = 12.5M physical CPU cores.

On a 256-core CPU: 12.5M cores / 256 cores per CPU = ~50K CPUs; Or on a 192-core CPU that would be 65K CPUs.

At the current public pricing, that is ~$800M.

B. DRAM
CPU can be aggressively oversubscribed because a VM that is waiting may consume almost no CPU. Memory is harder to oversubscribe because a live VM still needs to retain its working state.

Muse exposes roughly 8GB of RAM to the user environment, but one observed instance was actually using only around 3GB at the time of measurement.

25M live VMs * 3GB = 75PB of physical DRAM, call it ~75-100PB of physical DRAM feels like a reasonable base range.

At the current public pricing, that is ~$2B.

C. Sandbox power
~0.1 GW for the entire Muse sandbox / VM layer at 100M DAU.

------

2/ Inference
Muse’s personal computer executes tools and stores state locally, but the actual model runs on separate inference infrastructure. Meta’s Muse architecture

Energy per inference event
Microsoft’s 2026 study estimates that optimized frontier-scale inference consumes a median of approximately: 0.31Wh per normal query

But a long reasoning query with roughly 15x the token count consumes approximately 13x as much energy, or around: 4Wh per long reasoning query

The study specifically highlights reasoning and agentic workloads as significantly more energy intensive.
microsoft.com/en-us/research/publication/energ…

Sensitivity analysis on # reasoning-equivalent events per DAU per day

Suppose each active @Muse user generates the equivalent of 50 heavy inference events per day.

At 5Wh each:

100M users * 50 events/day * 5Wh = 25GWh/day

25GWh/day / 24 hours = ~1.0GW average power

So inference alone could require: ~1-2GW of average power

A 3-4GW Muse is entirely plausible. Maybe that’s why @Meta is rumored to be adding 7-10GW of compute next year.

------
The popular framing around Muse is that giving every user 2 vCPUs and 8GB of RAM creates an enormous CPU requirement. But the naive calculation materially exaggerates the CPU requirement because it treats logical VM allocation as dedicated physical infrastructure.

The more interesting conclusion is: Consumer agents may be a meaningful new demand driver for CPUs and conventional DRAM, but inference remains the real compute bottleneck. And as agents do more work, run longer trajectories and increasingly spawn other agents, inference demand can scale much faster than the number of users itself.

+++
Calling my peer review group: @bubbleboi @damnang2 @Midnight_Captl @FundaAI @fi56622380 . Feedback/ Pushbacks pls :).

++
Better formatted: robonomics.substack.com/p/agent-muse-compute-d…
♥ 1.0K · ⟲ 121 · 👁 593.4KView on X ↗
AI9/10

OpenAI Launches GPT-6 Sol and Luna With 50% Lower API Prices

OpenAI Launches GPT-6 Sol and Luna With 50% Lower API Prices▶

OpenAI Developers announced that GPT-6 Sol and Luna are launching today, with API prices 50% lower than GPT-5.6. The post positions Sol for building and Luna for scaling to production.

Original post · 1 min read
GPT-6 Sol and Luna just landed in Astra’s orbit.

Both launch today with API prices 50% lower than GPT-5.6.

Build with Sol. Scale with Luna. To production and beyond.
♥ 9.7K · ⟲ 752 · 👁 982.0KView on X ↗
AI5/10

Amjad Masad Predicts AI Will Make Software Effectively Open Source

Amjad Masad says AI-powered reverse engineering and decompilation are advancing rapidly and expects nearly all software to become de facto open source.

Original post · 1 min read
What’s happening in the AI-powered reverse engineering and decompilation is absolutely insane. Pretty soon all software will be de facto open-source.

AI is coming for everything and everyone.
♥ 8.6K · ⟲ 802 · 👁 585.9KView on X ↗
AI9/10

Anthropic Introduces Claude Opus 5.5 in New Claude 5.5 Model Family

Anthropic Introduces Claude Opus 5.5 in New Claude 5.5 Model Family▶

Claude announces Claude Opus 5.5, the first model in its new Claude 5.5 family. Anthropic says it performs at the level of Claude Fable 5.1 on most tasks and costs 40% less to run than Opus 5.

Original post · 1 min read
Introducing Claude Opus 5.5, the first model in our new Claude 5.5 family.

It performs at the level of Claude Fable 5.1 for most tasks, and costs 40% less to run than Opus 5.
♥ 97.1K · ⟲ 9.0K · 👁 28.1MView on X ↗
AI7/10

Jev Model Forecasts Booking Outcomes From 2,029 Real AI Receptionist Calls

Jev Model Forecasts Booking Outcomes From 2,029 Real AI Receptionist Calls▶

Muratcan Koylan reports a zero-shot experiment in which the Jev model analyzed structural features of 2,029 phone calls without audio or transcripts. It reached an AUC of 0.78 at the halfway point and ranked calls correctly 94% of the time near the end.

Original post · 1 min read
We gave Jev 2,029 real phone calls.

No transcripts or audio; it never heard a word. Our AI receptionist's calls were reduced to pure structure, meaning turns, tool calls, workflow stages and timing.

During the calls, Jev made 38,012 turn-level forecasts at 118 ms median latency, reviewed every call with five typed questions and produced 10,145 answers in 26 seconds with 256 requests in flight.

The experiment was zero-shot, with no fine-tuning or examples from our data. We compared Jev's forecasts with what actually happened in the EHR.

By the halfway point, Jev could meaningfully separate calls that would book from those that wouldn't (AUC 0.78), and near the end it ranked them correctly 94% of the time.

Even though Jev over-focused on visible errors our agent usually overcomes, it's still pretty incredible that it analyzed thousands of real calls in seconds for only $3.
♥ 2.1K · ⟲ 137 · 👁 372.2KView on X ↗
AI6/10

Aditya Agarwal Argues AI Gives Everyone Access to Top Experts

Aditya Agarwal argues that wealth cannot buy unlimited time with the world's best doctors or lawyers, and that AI both democratizes access to expertise and makes that expertise available without limit per person. He calls it intelligence too cheap to meter.

Original post · 1 min read
A common misconception is that if you are super rich, you can get unlimited access to the world's best doctor/lawyer/creative-professional etc.

The reality is that the world's leading cancer doctor will still see you for 20-30min if you have cancer no matter how much money you have.

This is why AI is so crazy.

It both democratizes access AND it makes the amount of time available unlimited for every individual.

This is the practical effect of intelligence too cheap to meter.
♥ 580 · ⟲ 33 · 👁 59.8KView on X ↗
AI7/10

Nvidia Alumnus Explains Shift From Copper to Optical Interconnects

Nvidia Alumnus Explains Shift From Copper to Optical Interconnects▶

In an interview shared by Molly O'Shea, former Nvidia engineer Yannick De Koninck says AI models outgrow single GPUs and copper is running out of bandwidth, pushing data centers toward optical interconnects. He now works at Thema, which is building photonics manufacturing in Europe.

Original post · 1 min read
“Copper is running out of steam.”

Yannick De Koninck, who helped develop silicon photonics at Nvidia, explains why AI models & agents are pushing data centers from copper to light:

“The models have gotten so large that they no longer fit on a single GPU. So what we need to do is interconnect multiple GPUs together to run these models.”

“As these GPUs get faster, they need more data, they need more data at a faster rate, and copper is running out of steam.”

“That's why we're transitioning to optical interconnects, which bring much higher data transfer bandwidths.”
Molly O’Shea @MollySOShea
NEW: Why This NVIDIA Engineer Left to Build @ThemaFoundry

Thema is building photonics manufacturing capacity in Europe

“If you look at an AI factory today, 50% of that is GPUs, but the other 50% is the technology to interconnect these GPUs.”

I sat down with Thema's CEO Herwig Van Hove & CTO Yannick De Koninck in Monaco to go deep on the photonics supply chain powering the next generation of AI infrastructure.

Yannick spent 5 years at NVIDIA, where he helped build its silicon photonics technology from scratch to product-ready maturity. He left what he calls the “golden palace” to join Thema…
♥ 106 · ⟲ 16 · 👁 12.5KView on X ↗
AI7/10

Gokul Rajaram Recommends Wafer AI Paper for Learning LLM Inference

Gokul Rajaram says he is using a paper recommended by Wafer AI to teach himself inference. The quoted post from @gpuemi says understanding the paper gives deep knowledge of batching, weight sharding and KV cache traffic.

Original post · 1 min read
Best way to learn inference. I’m using this to teach myself!

Thank you @wafer_ai
emilio andere @gpuemi
you'll know more about batching, weight sharding, and KV cache traffic than 99.92% of people if you fully understand this paper

follow and save to keep up with wafer ai performance engineering series twitter.com/wafer_ai/status/2105092095786762676
♥ 312 · ⟲ 27 · 👁 42.4KView on X ↗