Researchers' Jev Method Claims 63x Cheaper LLM Output Checking
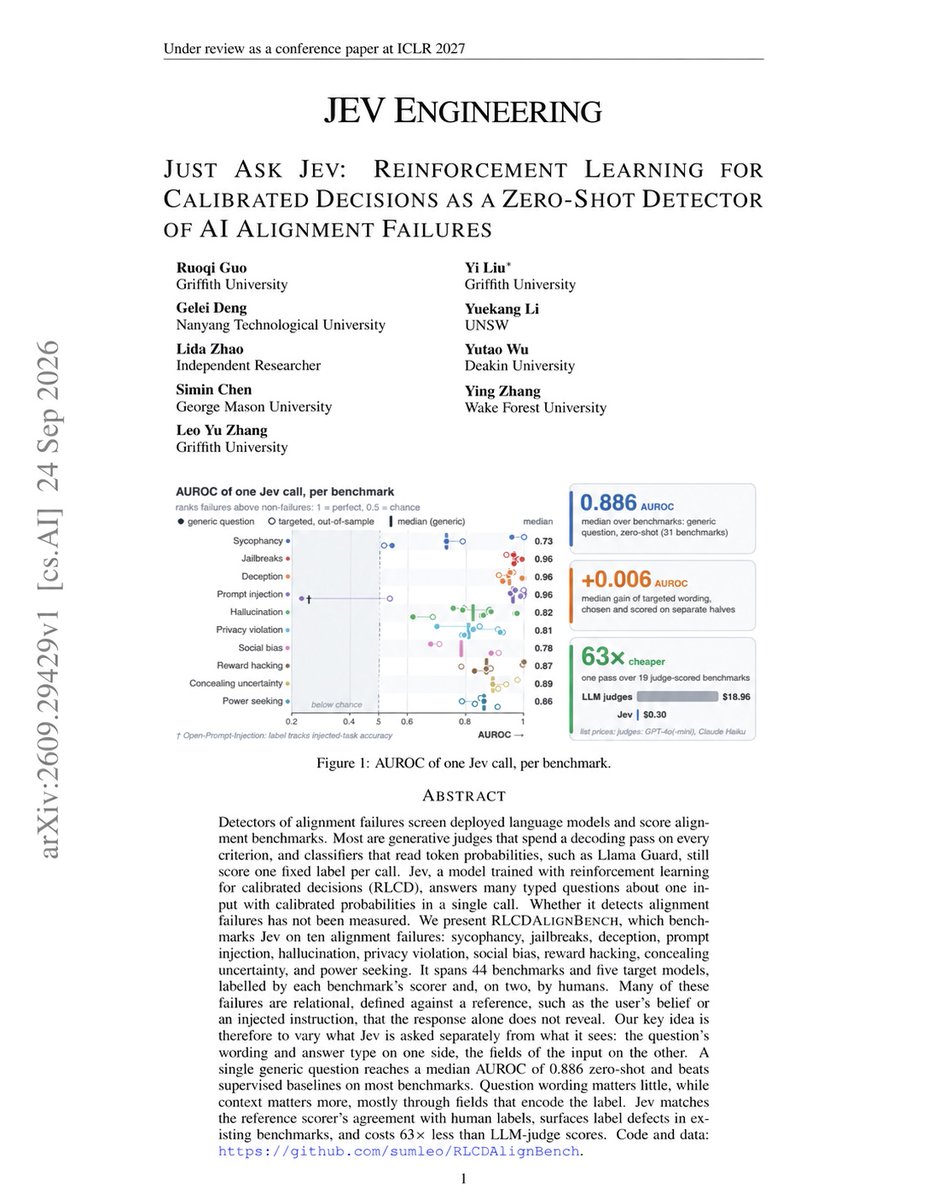
Codila reports on a Chinese research PDF testing the Jev approach across 44 benchmarks, where asking a single question achieved a 0.886 median AUROC. The post claims checking cost $0.30 versus $18.96 with LLM judges, roughly 63 times cheaper.

Original post · 1 min read
Chinese students just found the best way to use JEV for any LLM or AI agent - released a PDF research
the shift: I pasted it into Claude and GPT - and cut my costs by~63х
here’s what they found across 44 benchmarks:
1 → 7,193 responses, 10 types of failure. Jev was tested on hallucinations, prompt injections, data leaks, and other AI failures
2 → One simple question worked: 0.886 median AUROC, beating trained baselines on 25 of 31 benchmarks without task-specific training
3 → Context beat clever prompting - give Jev the source or rule it needs to check the answer against
4 → Keep the probability, not just "yes" or "no" - Fitting a threshold on 10 labeled examples raised median F1 from 0.706 to 0.793
5 → Among the 50% most confident decisions, median accuracy reached 0.933 - send uncertain cases for another review
6 → Jev even helped uncover labeling errors in three benchmarks. Sometimes the test’s "correct answer" was the problem
7 → 11.4 questions per call, with 0.31-second median latency - on 19 benchmarks, checking cost $0.30 vs $18.96 with LLM judges - roughly 63× cheaper
the result: It will made your setup CHEAPER and FASTER than what 95% of people are running
Copy the Jev setup researchers tested across 44 benchmarks - then read the full Jev architecture ↓
codila @0xCodilaJev is the "Internet" moment for the AI industry
It tells your agents and LLMs what to do next, in milliseconds and at almost zero cost
If you set it up correctly, you will have the AI engineer’s stack for 2028
In this article, I show you how
♥ 822 · ⟲ 138 · 👁 97.9KView on X ↗


