Wednesday, October 7, 2026ArchiveSearchAsk the paper

The Computomatix Times

All the posts fit to save — curated from @computomatix's bookmarks & likes on X

Search

289 stories

David Launches Jevgrep, a Context Collection CLI for Coding Agents

David Launches Jevgrep, a Context Collection CLI for Coding Agents▶

David announces jevgrep, a command-line research agent built on TypeSafe's Jev that finds relevant code by describing what it does. He claims it cuts coding agent costs by 40% on SWE-bench and links to the GitHub repository.

Original post · 1 min read
Introducing jevgrep - a research agent CLI powered by jev from @typesafeai that reduces your coding agent cost by 40% (verified on SWE-bench)

Make sure to use the built in skill so your coding agent knows to use jg for context collection github.com/dzhng/jevgrep
github.comGitHub - dzhng/jevgrep: Find code by asking what it does. A CLI for coding agents that uses Jev to discover relevant files and source context.Find code by asking what it does. A CLI for coding agents that uses Jev to discover relevant files and source context. - dzhng/jevgrep
♥ 4.9K · ⟲ 326 · 👁 447.7KView on X ↗

TypeSafe Releases Claude Code Skill for Building on Jev

TypeSafe Releases Claude Code Skill for Building on Jev

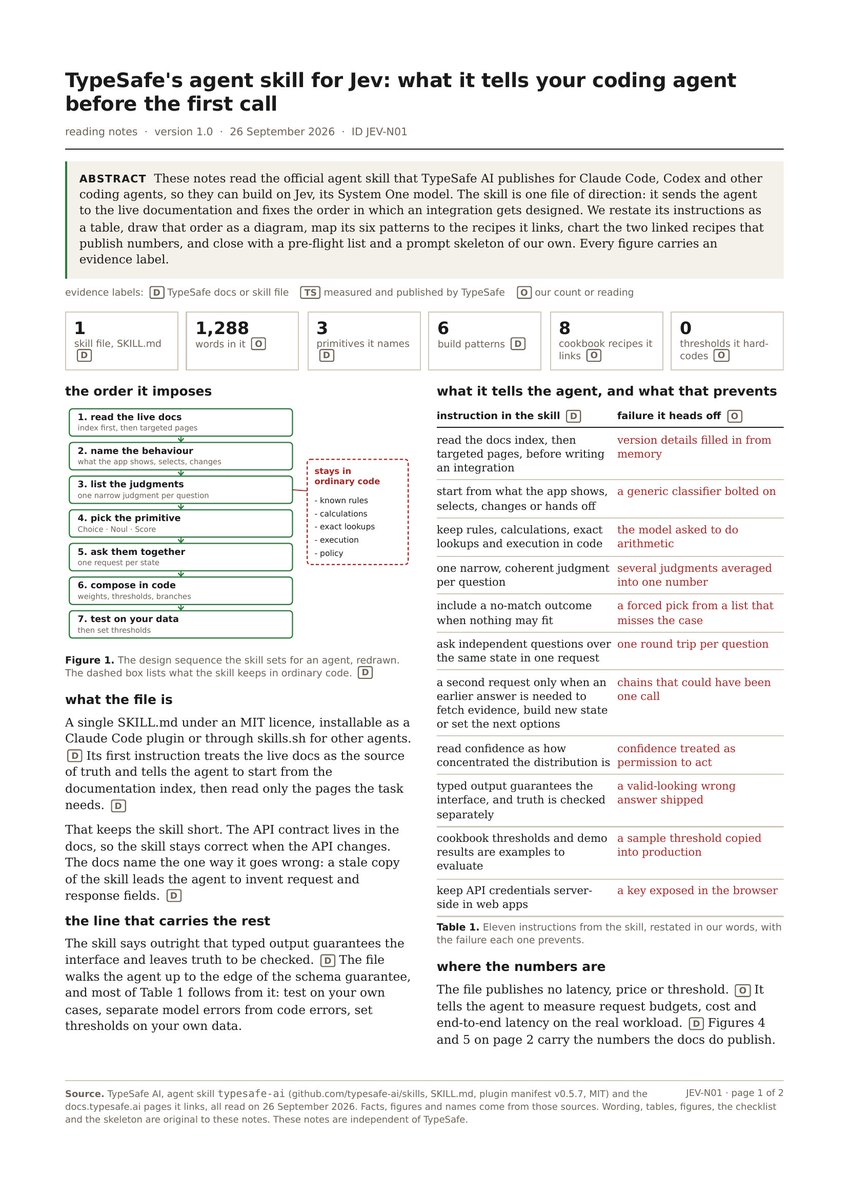
Mnimiy describes an official TypeSafe skill that teaches Claude Code to structure calls to Jev, batching questions into one request to cut costs by 12.2 times in TypeSafe's cookbook. The post also outlines fallback strategies for when Jev's 70-500 ms checks fail or go silent.

Original post · 1 min read
it's f*cking gold

TypeSafe just dropped the official skill that teaches Claude Code to build on Jev

left alone, coding agents ask Jev one question per call and guess the field names.

this skill rewires the order before a single line gets written:

docs -> behaviour -> judgments -> one request -> code decides

every rule in it, broken down on two pages:

> see the failure behind each of its 11 instructions
> pick Choice, Noul or Score in one glance
> paste the prompt skeleton straight into your agent

12.2x

the bill drop when 13 questions share one call, measured in TypeSafe's cookbook.

a short file that does a lot of the thinking for your agent.
Mnimiy @Mnilax
it's f*cking insane

Jev sat between GPT and me, killing every draft that broke my rules before i saw it. good setup.

then Jev did not answer. the agent decided silence was safer and stopped sending me anything at all. took a second agent to unstick it.

your checker needs a branch for the moment it goes quiet:

> let it through tagged unverified and keep moving
> hand the risky span to the big model
> park it in a queue and retry in a minute
> wake a human when the action is irreversible

70-500 ms

one Jev call, by TypeSafe's own number. a half-second checker still takes down the whole pipe…
♥ 2.2K · ⟲ 174 · 👁 291.7KView on X ↗

Trader Shares Claude-Generated Single-Page System From Zanger Rules

A trading account post says the author gave Claude the rules of Dan Zanger's trading method and asked for a simple system, and promises a one-page output, citing Zanger's reported growth from $10,775 to $18 million. The post itself contains no visible system details.

Original post · 1 min read
I gave Claude every rule from the world record holder's trading method and asked for one thing: build me a system simple enough to actually follow.

Dan Zanger turned $10,775 into $18 million in 18 months. Verified by Fortune magazine.

This is what it handed back, on a single page 👇
♥ 459 · ⟲ 32 · 👁 175.0KView on X ↗

Danny Postma Releases Skill for Generating 15-Second Motion Ads

motion-ad — danny.md

Danny Postma announces a reusable skill that turns a single prompt into a 15-second motion-graphics ad for a product, linking to a skill page on his site.

Original post · 1 min read
turned this into a skill anyone can use

one prompt → 15s motion ad for your product

danny.md/skills/motion-ad
Danny Postma @dannypostma
joining the opus 5.5 hype, what a time to be alive
danny.mdmotion-ad — danny.mdProduces short motion-graphics video ads (e.g.
♥ 578 · ⟲ 19 · 👁 85.9KView on X ↗

DHH Says Agents Make Trying Ideas Cheaper Than Planning

DHH argues that the opportunity cost of endless planning has risen because AI agents let builders try far more things, and says people learn faster by letting agents experiment.

Original post · 1 min read
This has never been more true. The opportunity cost of endless planning and contemplation just went way up. Agents allow you to just try vastly more stuff, so let them, and you'll learn way more, way faster.
♥ 5.3K · ⟲ 468 · 👁 255.2KView on X ↗

Claude Code Creator Boris Cherny Explains Prompting Opus 5.5

Claude Code Creator Boris Cherny Explains Prompting Opus 5.5▶

A post shares a 12-minute video in which Boris Cherny, creator of Claude Code, says Opus 5.5 needs less prompting than earlier models, and links to an article on prompting the model, which Anthropic released days earlier.

Original post · 1 min read
Boris Cherny, creator of Claude Code:

"Opus 5.5 does in a day what used to take your team a month. Most people will keep using it wrong."

In 12 minutes he explains why Opus 5.5 needs less prompting than any model before, and why your old detailed prompts now work against you.

Watch it, then read the article below on how to prompt Opus 5.5 👇
Rahul @sairahul1
Claude Opus 5.5 dropped 3 days ago.

And it might be the strongest model Anthropic has shipped yet.

But most people are still prompting it like older Claude models.

I turned Anthropic's latest guidance into a complete Opus 5.5 prompting masterclass:
♥ 710 · ⟲ 63 · 👁 151.0KView on X ↗

Free Open-Source Skill Adds Six Styles for App Screenshots

Free Open-Source Skill Adds Six Styles for App Screenshots▶

Parth Jadhav announces six new styles for an open-source agent skill that generates app store screenshots, which users can select or match to their app's existing look.

Original post · 1 min read
The best skill to generate Screenshots for your apps is getting even better 🔥

We've added 6 new styles which users can pick from, and trust me - They're beautiful !

And ofc, you can just tell the agent to "use the style of my app"

+ ITS FREE & OPEN SOURCE 🧵
♥ 533 · ⟲ 33 · 👁 83.8KView on X ↗

Creator Builds AI-Generated Video on Indian Civilization With Claude

Creator Builds AI-Generated Video on Indian Civilization With Claude▶

Siddharth Bulia shares a video on Indian civilization that was inspired by a viral example of Claude generating a Western civilization video. The post is a showcase of an AI video workflow.

Original post · 1 min read
Inspired by this and built a video on Indian Civilization :)

[You know, I'm something of a director myself.]
vittorio @IterIntellectus
holy shit
i asked claude to make a video on western civiization
♥ 53 · ⟲ 3 · 👁 58.0KView on X ↗

Shared Drive Offers 700 Markdown Summaries of 10,000 Books

A post shares a Google Drive folder containing 700 markdown files summarizing 10,000 books, which the author says will appeal to people running Claude on a VPS.

Original post · 1 min read
700 .md files summarizing 10K books

This is like catnip for people with Claude on a VPS
Gappy (Giuseppe Paleologo) @__paleologo
♥ 1.0K · ⟲ 42 · 👁 220.8KView on X ↗

Levie Argues Evals Will Gate Enterprise Adoption of AI Agents

Box CEO Aaron Levie argues enterprises cannot automate work they cannot measure, so evals are essential for adopting AI agents. He says domain-specific evals will become a major opportunity, and a quoted post notes data labeling firms expect Fortune 1000 customers to drive revenue and company evals may become proprietary IP.

Original post · 1 min read
You can’t automate what you can’t measure. This means that evals are one of the gates to diffusion of AI in the enterprise.

We can test our deterministic processes through software, but most enterprises have no useful way of understanding how their non-deterministic processes are working today. Specifically the work that agents are doing for them.

Evals are mission critical for enterprises adopting AI because you have no other way of knowing what’s working, what’s broken, what changed, what improved, what you can do more of, etc. if you don’t have a good sense of how agents work in your environment today. All changes, upgrades, and deployments are downstream from good evals.

Not only are we going to get vastly more domain specific evals over time for the labs and across the industry, but every enterprise will also need a clear sense of how agents are performing in their environment as well. Huge opportunity.
Alex Lieberman @businessbarista
Just spoke to one of the big data labeling businesses.

Few interesting insights:
- They predict the majority of their revenue will come from Fortune 1000 enterprises, not labs in a few years
- They believe every company will want to own their intelligence, but owning intelligence does not necessarily mean using open source models
- A company’s evals will become their main proprietary IP given the improvement in agent performance after properly setting up & running internal eval environments
- Most enterprises haven’t graduated from coding agents and it’s largely due to not having the proper e…
♥ 450 · ⟲ 51 · 👁 134.0KView on X ↗

DHH Says Models Can Also Handle Software Architecture

David Heinemeier Hansson responds to developers seeking to preserve architecture as a human domain, arguing that AI models are also very good at architectural work.

Original post · 1 min read
I understand the appeal in trying to find the first plausible fortress in our retreat from writing code, but if you think it's "architecture", I have bad news for you. The models are also very good at that.
♥ 6.5K · ⟲ 280 · 👁 614.7KView on X ↗

DHH Ports Omarchy Screensaver Engine From Rust to Assembly

DHH Ports Omarchy Screensaver Engine From Rust to Assembly▶

David Heinemeier Hansson reports porting the ttfx screensaver engine from Rust to x86-64 assembly, using Opus 5.5 for a one-shot translation, with the pull request claiming up to 17x speedup. The linked PR describes 9.8x faster than Rust and 322x faster than Python.

Original post · 1 min read
I ported the Omarchy screensaver engine (ttfx) from Rust to x86-64 assembler, and it's up to 17x faster!! One-shot translation by Opus 5.5. We keep drilling until the agentic drill bit hits bedrock! github.com/omacom/ttfx/pull/35/
github.comAdd an x86-64 assembly engine: 9.8x faster than Rust, 322x faster than Python by dhh · Pull Request #35 · omacom/ttfxAdds an x86-64 assembly engine for all 37 effects, linked into the Rust binary and picked automatically at runtime. It produces byte-identical output to the Rus
♥ 5.0K · ⟲ 209 · 👁 1.4MView on X ↗

Tobi Lutke Announces Cross-Platform Release of Disk Space Tool

Tobi Lutke Announces Cross-Platform Release of Disk Space Tool

Shopify CEO Tobi Lutke says a tool he built to find lost disk space is now fully cross-platform across major operating systems, a follow-up to an earlier post describing software as something you can wish into existence.

Original post · 1 min read
Now fully cross platform for all major operating systems
tobi lutke @tobi
Was wondering where my disk space went.
Therefore this exists now. You can simply wish software into existence.
♥ 1.3K · ⟲ 20 · 👁 104.1KView on X ↗

Researchers' Jev Method Claims 63x Cheaper LLM Output Checking

Researchers' Jev Method Claims 63x Cheaper LLM Output Checking

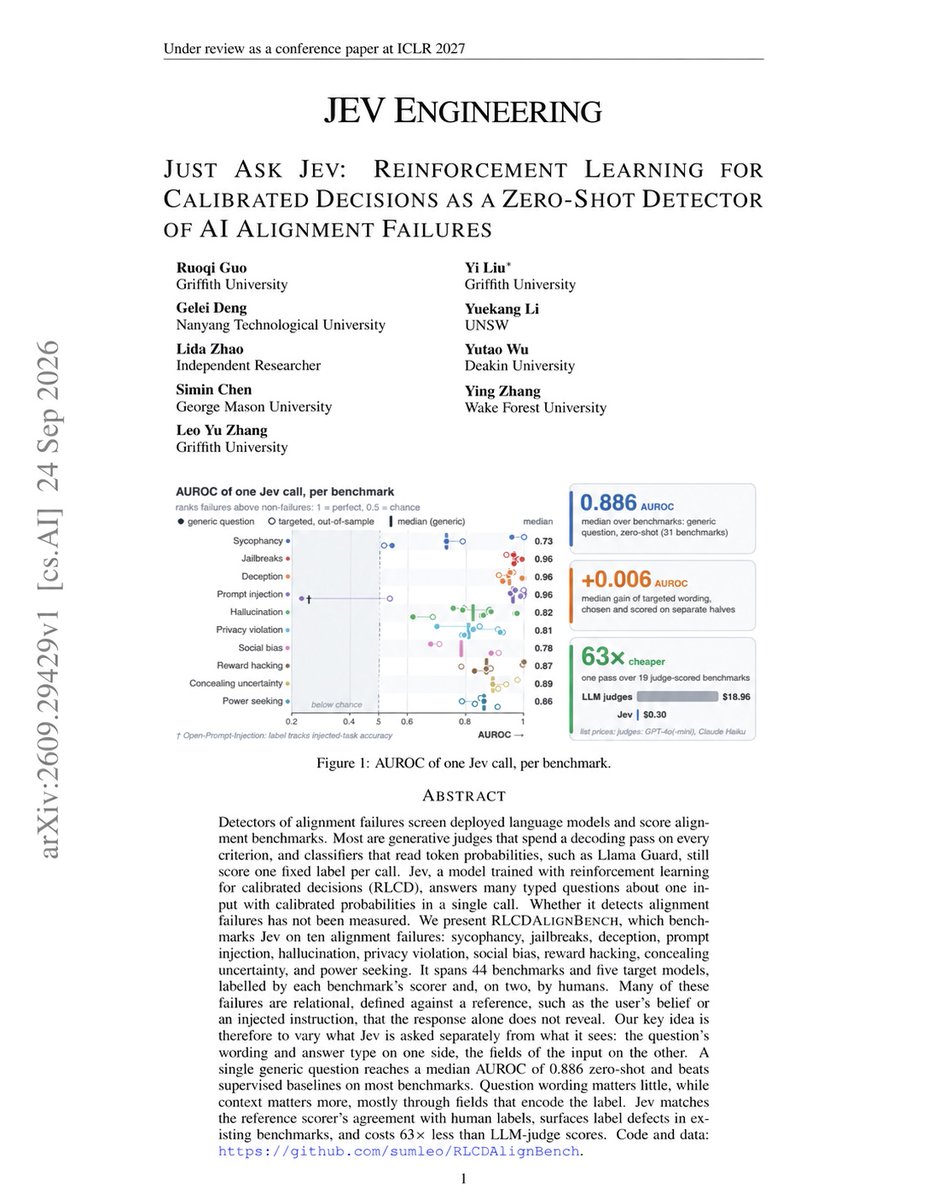
Codila reports on a Chinese research PDF testing the Jev approach across 44 benchmarks, where asking a single question achieved a 0.886 median AUROC. The post claims checking cost $0.30 versus $18.96 with LLM judges, roughly 63 times cheaper.

Original post · 1 min read
Chinese students just found the best way to use JEV for any LLM or AI agent - released a PDF research

the shift: I pasted it into Claude and GPT - and cut my costs by~63х

here’s what they found across 44 benchmarks:

1 → 7,193 responses, 10 types of failure. Jev was tested on hallucinations, prompt injections, data leaks, and other AI failures

2 → One simple question worked: 0.886 median AUROC, beating trained baselines on 25 of 31 benchmarks without task-specific training

3 → Context beat clever prompting - give Jev the source or rule it needs to check the answer against

4 → Keep the probability, not just "yes" or "no" - Fitting a threshold on 10 labeled examples raised median F1 from 0.706 to 0.793

5 → Among the 50% most confident decisions, median accuracy reached 0.933 - send uncertain cases for another review

6 → Jev even helped uncover labeling errors in three benchmarks. Sometimes the test’s "correct answer" was the problem

7 → 11.4 questions per call, with 0.31-second median latency - on 19 benchmarks, checking cost $0.30 vs $18.96 with LLM judges - roughly 63× cheaper

the result: It will made your setup CHEAPER and FASTER than what 95% of people are running

Copy the Jev setup researchers tested across 44 benchmarks - then read the full Jev architecture ↓
codila @0xCodila
Jev is the "Internet" moment for the AI industry

It tells your agents and LLMs what to do next, in milliseconds and at almost zero cost

If you set it up correctly, you will have the AI engineer’s stack for 2028

In this article, I show you how
♥ 822 · ⟲ 138 · 👁 97.9KView on X ↗

DHH Declares Hand Coding Economically Obsolete for Most Programmers

David Heinemeier Hansson argues that writing code by hand is no longer an economically viable skill for most programmers at most companies, a view Karthik Hariharan says most engineers saw coming and notes raises questions about hiring and training.

Original post · 1 min read
Most of us saw this coming over the last year, but @dhh weaves the narrative well. Hand coding is likely done for most software engineers.

We still have to figure out how to train and hire new software engineers though so maybe hand coding will live on in leetcoding for a while.
DHH @dhh
It's pencils down, people. Writing code by hand is no longer an economically viable skill for most programmers at most companies. But the future of making software has never been brighter. Don't you dare black pill this beautiful moment! youtube.com/watch?si=6FsfJXS22mk52gyu&v=vDjW_d…
♥ 48 · ⟲ 1 · 👁 7.7KView on X ↗

Microsoft Unveils Biggest Copilot Update, Adding Autopilot and Code

Microsoft Unveils Biggest Copilot Update, Adding Autopilot and Code▶

Satya Nadella announces a major Copilot overhaul framed as a new operating system for work, including a proactive enterprise agent, in-tenant app building, Chat and Cowork merged into Home, Office embedded in Copilot, and a proactive Today feed in Microsoft 365.

Original post · 1 min read
We’re building Copilot as a new OS for work that spans every model, every form factor, and every task. Today, we’re announcing our biggest update to Copilot to date, bringing four things together:

· Autopilot: proactive and long-running agent built for the enterprise
· Code: build apps with Copilot, hosted inside your company’s tenant
· Home: Chat + Cowork together
· Office: now fully embedded in Copilot (and Copilot embedded in Office, of course!)

Plus, you can invoke Copilot in Teams, and we’re introducing Today, a proactive experience that surfaces the most important information from across M365 without needing to ask for it.

The way we work is changing and so are our workflows. This update brings AI into that flow, from answering a question, to building an app, to getting work done on your behalf.
♥ 12.3K · ⟲ 1.6K · 👁 3.8MView on X ↗

Shopify CEO Tobi Lutke Shares Tool for Creating Software From Wishes

Shopify CEO Tobi Lutke Shares Tool for Creating Software From Wishes

Shopify CEO Tobi Lutke posts a photo with a playful note that he was looking for lost disk space, then announces a tool that lets users simply wish software into existence.

Original post · 1 min read
Was wondering where my disk space went.
Therefore this exists now. You can simply wish software into existence.
♥ 7.8K · ⟲ 260 · 👁 1.3MView on X ↗

Patrick OShaughnessy Highlights DHH Talk on Code Writing Shift

Patrick OShaughnessy Highlights DHH Talk on Code Writing Shift

Patrick OShaughnessy praises a talk in which DHH argues that writing code by hand is no longer economically viable for most programmers, drawing a parallel to how technology reduced photo-taking and predicting the same progression for code.

Original post · 1 min read
This talk is so, so good

Favorite idea—This photo shows what tech did to number of pictures taken.

Now same progression happening to code.

Then it’ll happen to…
DHH @dhh
It's pencils down, people. Writing code by hand is no longer an economically viable skill for most programmers at most companies. But the future of making software has never been brighter. Don't you dare black pill this beautiful moment! youtube.com/watch?si=6FsfJXS22mk52gyu&v=vDjW_d…
♥ 538 · ⟲ 41 · 👁 134.6KView on X ↗

Justine Moore Shares Prompting Tips for Seedance 2.5 Character Swaps

Justine Moore Shares Prompting Tips for Seedance 2.5 Character Swaps▶

Justine Moore shares techniques for Seedance 2.5 video character swaps, including using a reference video with character images, blurring faces via Codex to avoid rejections, swapping two characters at a time, and providing a detailed prompt. She references her AI remake of The Office.

Original post · 1 min read
Okay I think I've cracked the code on these.

Seedance 2.5 is very good if you upload a reference video + images of new characters and ask to swap.

In some cases the ref video will get rejected - so I just ask Codex to blur the faces and resubmit 😂

It's also best doing two characters at a time. For this one I did Dario and Jensen first and then re-ran it with Sam. Prompt below.

Edit the entire source video @ Video1.

Replace the viewer's FAR RIGHT performer with the man in @ Image1 in the same pink shirt and blue / gray hoodie. Keep the LEFT and MIDDLE performers the same.

The photos provide identity and wardrobe only.
The video provides motion, expressions, gestures, timing, interactions, camera cuts, framing, lighting and background.

Preserve the original performance as faithfully as possible. Do not swap positions or invent new movement or scene elements.
Justine Moore @venturetwins
Day 1 of recreating every episode of The Office but AI
♥ 489 · ⟲ 33 · 👁 65.8KView on X ↗

Wes Bos Details Unrestricted Features of Meta's Muse Assistant

Wes Bos Details Unrestricted Features of Meta's Muse Assistant

Developer Wes Bos shares findings from inspecting Meta's Muse, noting it can zip directories, ships with about 70 preloaded skills, deploys sites to Cloudflare, installs software freely, and has an optional email inbox feature.

Original post · 1 min read
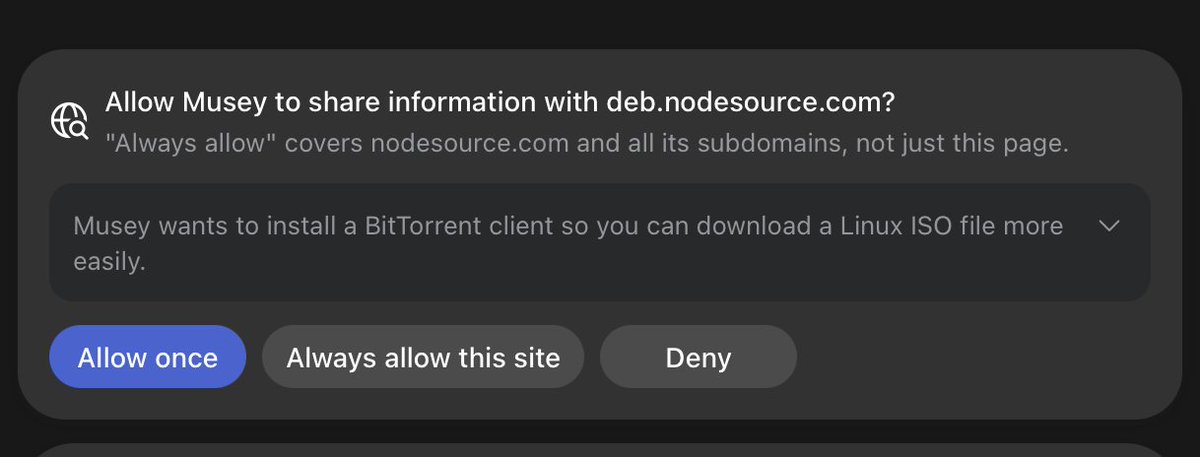
I cracked open Meta's Muse - here are some interesting bits 🔽

1. You can ask it for the entire contents of /opt/ and it will zip it up for you

2. There a ~70 preloaded skills and CLI for everything from spotify to instragram-cli

3. "Spaces" is their website builder that uses Tanstack, Bun and Tailwind. Sharing a site deploys it to Cloudflare

4. It will install anything - like a torrent client

5. It has it's own "Muse DB" with a skill to query its own memories/convos with strict guard rails

6. There are a few things not enabled on my account, including "muse mail" which will give muse an inbox and ability to send email

Generally impressed that you can just do anything - it's not limited or watered down like I would have imagined
♥ 2.0K · ⟲ 69 · 👁 199.9KView on X ↗

Deedy Demonstrates Fully Automated Video Summaries of Research Papers

Deedy Demonstrates Fully Automated Video Summaries of Research Papers▶

Deedy says Claude Opus 5.5 can generate an eight-minute, 3Blue1Brown-style explainer video from any research paper, using a summary of a paper on regularized recursive self-improvement of agent harnesses as an example.

Original post · 1 min read
You can now generate an entire 3blue1brown style video from any research paper with Opus 5.5.

Here’s a 8min video summary of “Regularized Recursive Self Improvement of Agent Harnesses”.

The 90%ile educational YouTuber is fully automated.
♥ 5.6K · ⟲ 398 · 👁 332.4KView on X ↗

Anthropic Offers Free Claude Code Credits Through October 7

Anthropic Offers Free Claude Code Credits Through October 7

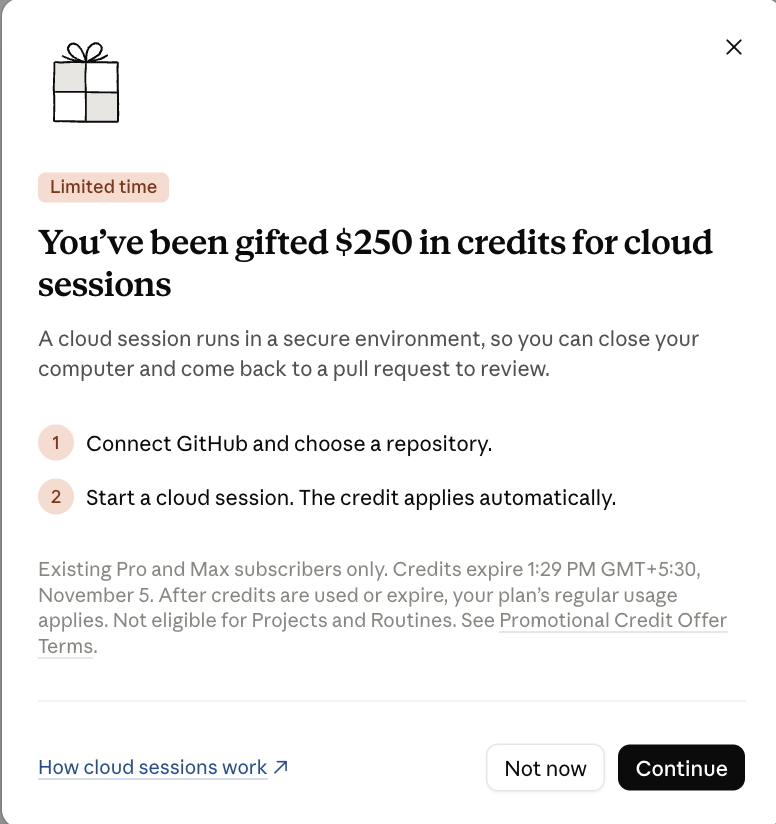
Claude's official developer account announced free credits, claimable via a link or the /claim-credit command in the CLI with a connected GitHub account. Claims are due by October 7, and terms apply.

Original post · 1 min read
Claude is handing out free credits 🫡
ClaudeDevs @ClaudeDevs
Follow the link below to claim the credit or run /claim-credit in the CLI. You’ll need GitHub connected to start a session. Claim by Oct 7. Terms apply.

claude.ai/code/claim-credit/10
♥ 8.8K · ⟲ 247 · 👁 2.8MView on X ↗

DHH Says Hand-Writing Code Is No Longer Economically Viable

Rails World 2026 Opening Keynote - DHH

David Heinemeier Hansson, creator of Ruby on Rails, argues that writing code by hand is no longer economically viable for most programmers at most companies. He frames this as a bright moment for software creation, in a Rails World 2026 keynote.

Original post · 1 min read
It's pencils down, people. Writing code by hand is no longer an economically viable skill for most programmers at most companies. But the future of making software has never been brighter. Don't you dare black pill this beautiful moment! youtube.com/watch?si=6FsfJXS22mk52gyu&v=vDjW_d…
youtube.comRails World 2026 Opening Keynote - DHHDHH opens Rails World 2026 in Austin with a keynote on the age of A...
♥ 8.9K · ⟲ 950 · 👁 2.9MView on X ↗

Anthropic Details How It Made claude.ai Three Times Faster

Claude

Boris Cherny highlights an Anthropic blog post describing how the team made claude.ai three times faster in two weeks using Claude to measure, debug and improve performance. The post includes prompts and methods for engineers optimizing their own apps.

Original post · 1 min read
If you've noticed how fast claude.ai/login and the Desktop app have become in the last few weeks, here's how we did it.

Lots of juicy learnings & techniques in the blog post for engineers working on speeding up your own apps.
ClaudeDevs @ClaudeDevs
We made claude​.ai 3x faster in two weeks.

Here’s how we use Claude to measure, debug and improve performance. Prompts and methods included.

claude.dev/blog/how-we-made-claude-ai-faster/
claude.aiClaudeClaude is Anthropic's AI, built for problem solvers. Tackle complex challenges, analyze data, write code, and think through your hardest work.
♥ 5.3K · ⟲ 168 · 👁 847.5KView on X ↗

Veed Open-Sources OpenEdit for Agent-Driven Video Editing

Veed Open-Sources OpenEdit for Agent-Driven Video Editing▶

Sabba Keynejad introduces OpenEdit, an open-source agent-driven pipeline for creating subtitles, motion graphics, slides and rendered videos. He argues the challenge is native editing with fonts, branding and repeatable templates, not generating video from code. A linked post by Deedy Das describes producing a launch video for about $2.

Original post · 1 min read
Generating a good video from code is not the problem.

The problem is how you edit it natively.

How you use use fonts, branding and build repeatable templates.

And that’s why we built OpenEdit.

github.com/veedstudio/open-edit
Deedy @deedydas
Opus 5.5 is incredible at instructional video generation.

I made this launch video for a inference startup in 1min for ~$2. Videos like these used to take weeks if not months and a lot of coordination with agencies and 1000x the costs.

Humans broadly prefer video to text. This changes the substrate of communication. These videos actually help communicate technical ideas in seconds (photorealistic video gen like Seedance is not very useful here).
- changes how often marketing should be talking about products and launches
- change how sales people can talk about technical products to their cus…
github.comGitHub - veedstudio/open-edit: Open-source, agent-driven editing pipeline: create subtitles, motion graphics, slides, edit and render videos.Open-source, agent-driven editing pipeline: create subtitles, motion graphics, slides, edit and render videos. - veedstudio/open-edit
♥ 297 · ⟲ 5 · 👁 50.6KView on X ↗

Cursor Engineer Shares Prompt for Improving Agent Token Efficiency

Eric Zakariasson shares a detailed prompt based on Cursor's experience for optimizing an LLM agent harness's token efficiency without hurting task quality. It covers measuring cost per completed task, weighting token billing types, and avoiding prompt patterns that make models reluctant to work.

Original post · 15 min read
here's a prompt to improve your agent harness based on what we've learned at cursor. enjoy

# Improve this agent harness's token efficiency

You're working on an LLM agent harness: the system prompt, tool definitions, request assembly, context caching, compaction, and retrieval, and how work is split across agents. Make the agent's runs cheaper without making it worse at its job.

- Objective: lower price-weighted token cost per completed task.
- Constraint: no measurable drop in task quality.

Measure per task, not per request. Every turn resends the prefix (tools, instructions, setup, and the conversation so far), so a change that shrinks each request but adds turns can cost more. Weight tokens by billing type: output, uncached input, and cached input are priced very differently.

Work in this order: map the harness and measure the baseline, rank the opportunities, make the changes that are safe to make directly, put the rest behind flags or in proposals, then report.

Figures below come from one team's production coding agent and its multi-agent experiments. Use them to gauge magnitude, not as targets. One round of these changes (prompt trimming, tool offloading, cache layout, sparse line numbers, subagent tuning) cut that team's overall token cost about 7% with no loss in quality. The larger percentages apply only to the part of the request each change touched.

## Principles

1. Change what the harness sends, not how hard the model tries. Don't ask the model to conserve tokens. A harness that told its model to "take care to preserve tokens and not be wasteful" found it grew reluctant to take on ambitious tasks and sometimes quit, saying it wasn't supposed to waste tokens.
2. Capable models need definitions, not commands. Lists of "DO NOT", "You must", and "Important", and guards against older models' habits, can usually be replaced with plain descriptions of what each tool does. One team cut about two-thirds of its system prompt this way, and the shorter prompt worked across model families. Instruct only on what the model can't know (the product, the environment, the user's processes) and on quirks you've seen in transcripts.
3. Static context is for what most turns need. Everything else should be discoverable when needed. Less up-front context also means less confusing or contradictory information.
4. Expect removals to win. Guardrails written for weaker models, coordination steps that became bottlenecks, and prompting for behavior the model now does on its own all cost tokens.
5. Real usage decides. Evals are a fast proxy, but they skew toward hard problems and miss the real mix of requests.

## 1. Map the harness and measure the baseline

Find:

- Where requests are assembled, the system prompt, and tool schemas. If a framework or SDK builds requests, find its hooks for message order, cache control, and tool loading.
- How tool results are formatted, and how history is kept, trimmed, or summarized.
- How subagents or parallel agents are spawned, if any.
- Which models and provider APIs are used. From the provider's docs, get the prompt caching behavior (automatic or explicit breakpoints, TTL, minimum cacheable length) and the prices for output, uncached input, and cached input.
- Existing logging, token accounting, and evals.

If the harness doesn't record per-request token usage by billing type and cache hits, add that first. Everything later depends on it.

Then render a few real requests (from logs, or by running representative tasks) and count tokens per section with the model's tokenizer or the API's usage fields. Produce:

- Cost share by source × billing type. Sources: system prompt, tool definitions, skill/rule/integration descriptions, user messages, file reads, search results, command and other tool output, history, summaries, subagents.
- Static tokens per request, cache hit rate, and turns per task.
- Per tool: the share of runs that call it at least once, and its error rate.

Read the rendered requests, not just the templates. Duplication, leaked volatile values, and misordered blocks only show up there.

Rank opportunities by share of spend × fraction removable ÷ quality risk.

## 2. System prompt and injected context

Label every instruction:

- Keep: product or environment knowledge the model can't infer, fixes for quirks seen in this model's transcripts, and rules a mode depends on.
- Rewrite: commands and emphasis into plain descriptions. Reminders into constraints: "No TODOs, no partial implementations" works better than "remember to finish implementations." Vague quantities into ranges: "generate 20–100 tasks" gets far more ambitious behavior than "generate many tasks."
- Delete: things capable models do by default, guards against behavior you haven't seen from this model, text that repeats tool descriptions, and lines that could contradict a user request. Models trained to rank system instructions above user messages will side with the system prompt.
- Move: anything per-user or per-request (date, environment, repo state, lists of skills or subagents, user rules) into a user-role setup message after the cache boundary.

Audit other injected context the same way. As models improved, the team behind these figures dropped directory trees, pre-retrieved snippets, compressed copies of attached files, lint errors injected after every edit, forced expansion of short file reads, and caps on tool calls per turn. They kept small, high-value facts: OS, repo status, and open or recently viewed files.

Skip checklists for open-ended work. The model optimizes the listed items and deprioritizes everything else.

## 3. Tool definitions

Tool schemas ride along on every request. Most tools beyond the core set were each needed in under 20% of conversations, and moving them out of static context cut tool-description tokens 60%. Doing the same for integration tools (such as MCP servers), with names in context and full schemas in one folder per server that the agent can search with grep or jq, cut total tokens 46.9% in sessions that used them.

- Keep in static context: high-frequency tools (for a coding agent: read, search, edit, shell), tools the model tries to call even when they're absent, and tools a mode depends on.
- Offload the rest: leave a name or one-line pointer and make the full schema discoverable on demand. Group related tools so they load together, and put status (such as "needs re-authentication") where the agent will see it.
- Tighten what remains: describe behavior and arguments, and drop usage lectures.
- Pick the split by testing a few configurations and tracking tokens, cost, latency, tool-call errors, and task success.

## 4. Cache layout

Order each request so the reusable prefix is as long as possible:

`tool definitions → system instructions → [breakpoint] → setup message (skills, subagents, rules, environment) → [breakpoint] → conversation`

- Keep the prefix byte-identical across turns. Use deterministic tool order and serialization, put timestamps and IDs after the boundary, and don't rewrite earlier messages except when compacting.
- Use explicit breakpoints if the provider supports them. Otherwise rely on automatic prefix caching with the stable part first. Respect TTL and minimum-length rules.
- Switching models mid-conversation throws away the cache (caches are per model and provider) and hands the new model a history it didn't write. When a different model is needed, run it as a subagent with fresh context.

Explicit breakpoints plus moving per-request setup after them cut cold cache misses 20%.

## 5. Tool results and other context added during a run

- Large outputs (commands, integrations, logs): write them to a file and return the path, size, and a short tail. The agent can tail, grep, or read ranges for more. Truncating loses data, and inlining bloats every later request. Treat long-running terminal sessions the same way.
- High-volume formats: look for overhead repeated on every line or item. Numbering every 10th line of a file read instead of every line cut cache-read tokens 1.6% without hurting citation accuracy. Each number costs 3–5 tokens, and agents read tens of thousands of lines per session. Also check repeated absolute paths, verbose JSON keys, ANSI codes, progress bars, and repeated headers.
- Good retrieval saves exploration turns. Adding semantic search alongside grep raised codebase question-answering accuracy 12.5% on average and cut the iterations users needed.
- Tool errors waste tokens and leave confusing debris in context. Classify expected errors (invalid arguments, unexpected environment, provider error, timeout, user abort), treat unknown errors as harness bugs, and track rates per tool and per model. One focused effort along these lines cut unexpected tool errors 10×.

## 6. Long runs: compaction, subagents, and model mix

- Compaction: keep the summarization prompt short and the summary compact, carry forward plan state and remaining tasks, and save the full history to a file the agent can search for details the summary dropped. A model trained to self-summarize from a one-line prompt wrote ~1k-token summaries with half the compaction error of a multi-thousand-token prompt that produced 5k+ token summaries. Untrained models may need more guidance, so test how short you can go. A more expensive summarization model made a negligible difference.
- Scratchpads and running notes: rewrite them instead of appending. For repeated work in one environment, a small agent-maintained notes file with a line budget, loaded at start, is a promising way to shorten later runs.
- Subagents: fresh context keeps the parent lean, but isolation adds coordination cost (duplicate or stale work). If the model already delegates on its own, remove prompting that pushes it to. Have subagents return short handoffs: what was done, findings, concerns, and deviations. A subagent should use a different model only when the user or harness says so.
- Model mix: in large multi-agent runs, workers used at least 69% of tokens, and over 90% in most runs. A frontier planner with cheap workers matched a frontier model doing everything at about one-eighth the cost. Planner choice still changes worker spend. One planner that cost less on its own saw its workers use several times more tokens, and the run cost more overall. Measure the whole tree.
- Routing and reasoning effort: send simple turns to a cheaper model or lower effort, and upgrade only when a stronger model is clearly better. A router built this way matched or beat single frontier models on user satisfaction at 41–68% lower cost.
- Reasoning continuity: if the API returns reasoning items (including encrypted ones), pass them back on later turns and alert when they go missing. Dropping them cost one reasoning model 30% on a coding benchmark, and it burned tokens reconstructing its plan.

## 7. Fit the harness to each model

Adapt to what each model was trained on instead of forcing one shape on all of them. If you've tuned the harness for a similar model, start from that version.

- Edit format: use the one the model was trained on (for example, patch-style or search-and-replace). An unfamiliar format costs extra reasoning tokens and causes more mistakes.
- Shell or tools: shell-first models fall back to `cat` or inline scripts. Name tools after their shell equivalents (such as `rg`), and if needed add: "If a tool exists for an action, prefer to use the tool instead of shell commands (e.g. read_file over `cat`)."
- Literalness: some model families follow instructions literally and others tolerate imprecision. Some spiral on emphasized wording. Strip caps and emphasis for literal models.
- Triggers: some models ignore a tool until told when to use it. A literal trigger works: "After substantive edits, use the <lint tool> to check recently edited files for linter errors. If you've introduced any, fix them if you can easily figure out how."
- Progress updates: if a model reports progress through reasoning summaries, keep them to 1–2 sentences that note new findings or a change of tactic, and remove instructions about messaging mid-turn.
- Quirks worth a targeted line: hedging or refusing as context fills ("context anxiety"), declaring completion early, stopping to ask permission, and calling tools that don't exist.

Tie each added instruction to the transcript behavior it fixes. Re-audit when models change, since guidance one version needed can be dead weight for the next.

## 8. Validate

- Offline: run a fixed set of realistic tasks before and after, ideally drawn from real usage and phrased the way users actually write (short and ambiguous). Compare task success, tokens, cost per task, turns, and tool errors. Don't ship a change that lowers success.
- Online, if you have users: A/B test each change or small bundle. The primary metric is cost per completed task. Guardrails are task success signals, tool-call errors, latency, turns per task, and cache hit rate. For a coding agent, a good success signal is how much agent-written code survives over time. In general, check whether the user's next message moves on or reports a problem.
- Ship only when cost drops and no guardrail regresses beyond noise. Record null results.

## What to change directly and what to propose

- Change directly, each in its own revertible commit: token and cache telemetry, deterministic serialization and tool order, moving volatile content out of the cached prefix, explicit cache breakpoints, writing large outputs to files instead of truncating, passing back reasoning items that are being dropped, and fixes for recurring tool errors.
- Change behind a flag so it can be tested: system prompt edits, tool offloading, output format changes, compaction changes, and subagent prompting.
- Propose only: changes to which models run, routing, reasoning-effort defaults, or how work is split across agents.

## Traps

- Asking the model to use fewer tokens or do less.
- Truncating tool output.
- Dropping reasoning items to save input tokens.
- Volatile content in the cached prefix, or tool order that changes between requests.
- Offloading a tool the model needs on the first turn or tries to call when it's missing.
- Emphasis-heavy prompts (MUST, NEVER, IMPORTANT, all caps), especially with literal models.
- Forcing a terser output format than the model was trained on. Fewer output tokens can mean less thinking and worse results.
- Optimizing raw token counts instead of cost, per request instead of per task, or evals instead of real usage.
- Switching models mid-conversation to save money.
- Adding coordination layers that become bottlenecks.

## Report back with

1. The harness map and baseline: cost by source × billing type, with the biggest sources called out.
2. A ranked list of changes: layer, what changes, estimated savings and how you estimated them, quality risk, how to validate, and how to roll back.
3. The changes you made, including a system prompt diff with a keep, rewrite, delete, or move reason for each line.
4. A test plan for the flagged changes.
5. Gaps: anything you couldn't find or measure.
♥ 3.3K · ⟲ 148 · 👁 353.1KView on X ↗

Vercel Launches Drives for Sandbox in Public Beta

Guillermo Rauch argues successful AI agents need separated brain, hands and files components, and announces Vercel Drives, persistent storage for Vercel Sandbox now in public beta. Drives allow up to four mounts per sandbox and 16 TiB per Drive.

Original post · 1 min read
Muse, Instinct, OpenClaw, Claude Code…
All successful agents have 3 key components:

🧠 Brain → model, harness (logic)
👐 Hands → tools, computer, browser
🗃️ Files → memories, skills, repos

The 'easy' way is to throw all these in 1 stateful computer (a Mac Mini)

Like, you run 𝚌𝚕𝚊𝚞𝚍𝚎 or 𝚏𝚡 in your mac, you keep it running all day with 𝚌𝚊𝚏𝚏𝚎𝚒𝚗𝚊𝚝𝚎, it has storage, and CLIs and apps installed.

But if you want to cost-efficiently run agents in the cloud, you actually start breaking down these parts.

🧠 The harness can run in Fluid compute. To make it reliable across restarts, rollouts, crashes, you make its event log durable using Workflow.

👐 The hands can be a dedicated browser fleet like Browserbase/Kernel, a computer like Sandbox, and even more efficient lightweight tools like just-bash.

🗃️ 🆕 What was missing was a way to also decouple storage. Imagine you want to run a memory consolidation cron job every night ("dreaming"). You can read/write to the files directly without 'booting up' the agent's full computer.

Today we're introducing the perfect companion to Sandbox: Drives. We shipped the computer for agents, now we're giving you the 'external disk' you can attach at will. It's early, and we'll be expanding capabilities here quickly.

Btw, breaking apart the agent into these independent parts not only optimizes costs in a big way, it also *massively* improves security and auditability. I'd argue you can't even run a secure agent otherwise!
Vercel Developers @vercel_dev
Vercel Sandbox now has persistent storage with Drives, in public beta on every plan.

▪︎ Store agent workspaces, data, models, deps
▪︎ Read snapshots across parallel sandboxes
▪︎ Mount up to four Drives per sandbox
▪︎ Up to 16 TiB per Drive

vercel.com/changelog/drives-for-vercel-sandbox…
♥ 2.3K · ⟲ 138 · 👁 262.7KView on X ↗

Hiten Shah Highlights Muse Permission Controls for Network Protocols

Hiten Shah Highlights Muse Permission Controls for Network Protocols

Hiten Shah shows a permission screen from the consumer AI agent Muse that exposes controls for SSH, SMTP, DNS, TCP and other protocols. He notes users can block protocols or require approval per connection and is hosting an AI Permissions 101 session.

Original post · 1 min read
Muse is a consumer AI agent.

This is one of its permission screens.

It exposes controls for outbound SSH, SMTP, IMAP/POP3, database connections, FTP, DNS, TCP and UDP.

You can block a protocol entirely or let Muse ask before each connection.

Friday at 10 AM PT I’m doing AI Permissions 101.

hiten.com/ai-permissions-101
♥ 137 · ⟲ 9 · 👁 18.1KView on X ↗

Google Gemma Team Releases DiffusionGemma-Jev Endpoint on Cloud Run

Linus Ekenstam notes that frontier labs are rapidly releasing JEV forks, citing Google's Gemma team's djev. A linked Google post and GitHub repo describe deploying a Jev API-compatible endpoint on Cloud Run with one command.

Original post · 1 min read
I love seeing how fast the frontier labs are jumping in on creating forks.

Just today we’ve seen omni-jev and now djev from Google Gemma team.

It will be clear in a few weeks, just how powerful JEV is going to be inside harnesses and applications.
Google Gemma @googlegemma
Deploying DiffusionGemma-Jev (djev) just got a lot easier. You can now spin up a Jev API-compatible endpoint on Google Cloud Run using a single command.

Performance is solid: ~35-60 ms for single step latency and batch@32 is ~100-123 requests/sec.

It's a straightforward way to experiment without needing your own GPU. Runs at roughly $3/hr and drops to $0 when idle.

Get the code and instructions here: github.com/taeold/djev-run
♥ 67 · ⟲ 7 · 👁 18.2KView on X ↗

Danny Postma Rebuilds Landing Page With Nine AI Agent Skills

Danny Postma Rebuilds Landing Page With Nine AI Agent Skills

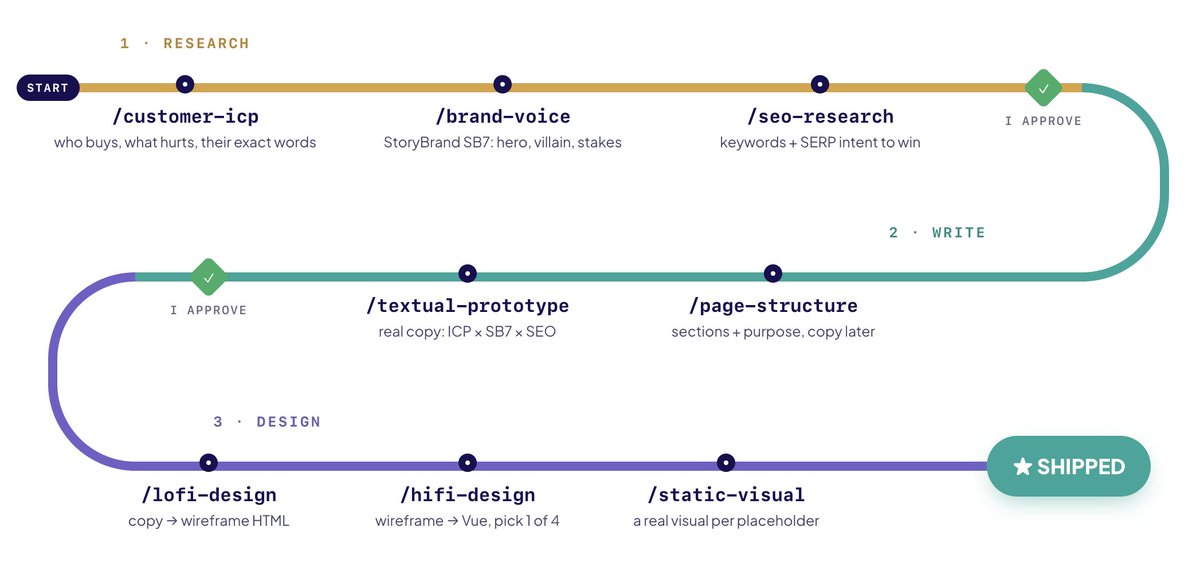
Danny Postma says he rebuilt his landing page using AI agents by creating nine reusable skills rather than one-shot prompting. He reports a 34% higher conversion rate and is considering turning the skills into a course.

Original post · 1 min read
A few weeks ago I rebuilt my landing page with AI agents.

No one-shot. I created 9 skills instead from all my years of knowledge to speed up my time.

Test just finished w/ 34% higher conversion rate 🚀

Wondering if I should turn these skills into a course for your AI agents 🤔
♥ 449 · ⟲ 9 · 👁 30.0KView on X ↗